7.0.1
Highlights
We are delighted to announce notable enhancements and updates in Healthcare NLP 7.0.1. The headline addition is DecisionModel, a new annotator that classifies the de-identified output of your pipeline, one decision per document, delivered with the PHI Guard model family. PHI Guard answers the question every de-identification project eventually has to answer at scale: is any PHI left in the de-identified output, and how serious is it? It can also tell which original notes hold any PHI at all, before de-identification. Instead of relying only on manual review of samples, you can now score every de-identified document, release the ones that pass, and send the rest to review. For PHI leak detection, PHI Guard v0.7 reaches a PR-AUC of 0.986 on de-identified clinical notes at 6.4 ms per note on one CPU thread.
The release also brings a set of de-identification enhancements that apply across the de-identification annotators (consistent fakes for possessive names, timestamps shifted with their time kept, date shifts in both directions, a configurable list of restricted ZIP code prefixes and safer handling of unusual ZIP values), and a major upgrade of FHIR de-identification for real-world FHIR data: free text inside resources, rules by data type, removing and keeping elements, one consistent date shift per patient, the HIPAA 90+ age rule, audit logs and traceability tags. CDA and HL7 v2 de-identification receive matching improvements. Annotation2Training and PipelineTracer become easier to use, and pretrained models now download in parallel, with byte-accurate progress.
DecisionModelwith PHI Guard — seven CPU models that classify de-identified output for residual PHI leaks, harmful leaks and PHI exposure before it is shared, and original notes for PHI presence- De-Identification enhancements — consistent fakes for possessive names (
Carter's), timestamp-aware date shifting, negative random date shifts (setMinRandomDisplacementDays), configurable restricted ZIP code prefixes and safer ZIP masking - FHIR de-identification upgrade — free text inside resources, data type rules,
REMOVE/KEEP/REMOVE_BASE64actions, per-patient date shifting, HIPAA age rules, output logs, traceability tags and free-text extraction for annotation - CDA and HL7 v2 de-identification improvements — header-aware tables, removing values, year-only dates, a random date shift range and free-text extraction
Annotation2Trainingkeeps the annotated chunks next to the generated NER training dataPipelineTracersupportsPretrainedZeroShotMultiTaskandMultiAnnotationSplitter- Faster pretrained model downloads — parallel downloads with byte-accurate progress, from Spark NLP 7.0.1
- Bug fixes — FHIR serialization after
deidentify, choice-type paths, nested narrative tables and placeholder dates - PHI Guard benchmarks — leak, harmful-leak, raw-note, richness and speed results, and residual leak detection on the public MedDeID synthetic benchmark
- Medical Decision Models (DMs) benchmark — task performance across nine clinical task areas, and cost analysis
- New Blog Posts & Technical Deep Dives
- Updated Notebooks And Demonstrations For Making Healthcare NLP Easier To Navigate And Understand
- New DecisionModel Notebook
- The addition and update of numerous new clinical models and pipelines continue to reinforce our offering in the healthcare domain
These enhancements will elevate your experience with Healthcare NLP, enabling more efficient, accurate, and streamlined analysis of healthcare-related natural language data.
🌟 Spotlight: DecisionModel and PHI Guard — Check Every Document Before It Leaves
De-identification pipelines are highly accurate, but no automated de-identification is perfect, and the teams that release de-identified data are the ones who have to answer for the exceptions. Until now, finding the few documents that still carry PHI meant reviewing samples by hand or running a second extraction pass and interpreting its output.
DecisionModel closes that gap. It is a new Healthcare NLP annotator that reads the de-identified (masked) output of your de-identification pipeline and returns a single classification for each document: does it still leak PHI, is the leak harmful, and how much PHI does it expose — with the probability in the metadata. The same models can also classify the original notes before de-identification, to tell which ones hold any PHI at all. DecisionModel runs natively in your Spark NLP pipelines, with batching, and is saved and loaded with the pipeline like any other stage.
DecisionModel is built for John Snow Labs’ Medical Decision Models (DMs): compact, task-optimized models that answer typed questions about clinical text — pick one option, answer yes or no with a probability, or choose an ordered level. Task-optimized models consistently outperform general-purpose models on focused clinical decisions, and they are small enough to deploy privately.
In this release, DecisionModel runs the PHI Guard family (getModelType() returns phi-guard): seven models that detect PHI in de-identified and raw notes, in single-purpose and all-in-one versions. All of them run on CPU with ONNX and need about 1 GB of RAM. For PHI leak detection, PHI Guard v0.7 reaches a PR-AUC of 0.986 on de-identified clinical notes at 6.4 ms per note on one CPU thread. The family is bound to the model you download, so a loaded model always runs the graph it was built for and cannot be switched to another family by a parameter.
Please see DecisionModel notebook
PHI Guard covers four questions, called modes:
| Mode | Question it answers | Score it on | Labels | Score in metadata |
|---|---|---|---|---|
leak |
Is any PHI left after de-identification? | the de-identified document | PHI_LEAK, NO_PHI_LEAK |
phi_leak_prob |
harmful |
Is a remaining leak a harmful one? | the de-identified document | HARMFUL_PHI_LEAK, NO_HARMFUL_PHI_LEAK |
harmful_leak_prob |
richness |
How much PHI does the note expose? | the de-identified document (or the original note) | NONE, TRACE, LOW, MODERATE, HIGH, VERY_HIGH, SATURATED (levels 0 to 6) |
level, score_1 … score_6 |
raw |
Does the original note contain PHI? | the original note, before de-identification | PHI_PRESENT, NO_PHI_PRESENT |
phi_present_prob |
A harmful leak is always a leak too: harmful_leak_prob never exceeds the leak probability of the same document. In richness mode, score_1 … score_6 are the probabilities that the document reaches at least each of the six levels above NONE; they never increase from one level to the next, and level is the number of them that are 0.5 or higher, which gives the label.
This turns PHI checks into a regular pipeline step. Typical uses are:
- A quality gate after de-identification — add
leak(andharmful) at the end of your de-identification pipeline, release the documents that pass, and route the rest to human review. - Monitoring — track
richnessover batches to see how much PHI information is left in your de-identified output, and whether a change in the source data or in the pipeline moved it. - Triage before de-identification — use
rawon the original notes to find the documents that need de-identification at all, or to prioritize them.
Pretrained PHI Guard models
| Model Name | Model | Mode | Best for | Parameters | Size |
|---|---|---|---|---|---|
phi_guard_3m_v0.7 |
PHI Guard v0.7 | raw, leak, harmful, richness |
Leak, harm, richness and raw in one model; the default of DecisionModel.pretrained() |
about 3 million | 14.1 MB |
phi_guard_870k_v0.7_fast |
PHI Guard v0.7 Fast | raw, leak, harmful, richness |
The same four modes, about 5x faster | about 870 thousand | 3.6 MB |
phi_guard_3m_v0.6 |
PHI Guard v0.6 | leak |
Gate de-identified notes | about 3 million | 12.0 MB |
phi_guard_850k_v0.6_fast |
PHI Guard v0.6 Fast | leak |
The same gate when speed matters most | about 850 thousand | 3.5 MB |
phi_guard_3m_v0.6_masked |
PHI Guard Masked v0.6 | leak |
De-identified gate with a final fine-tuning step | about 3 million | 12.0 MB |
phi_guard_3m_v0.6_raw |
PHI Guard Raw v0.6 | raw |
Route or skip PHI-free raw notes | about 3 million | 12.0 MB |
phi_guard_3m_v0.6_richness |
PHI Guard Richness v0.6 | richness |
How much PHI a note exposes (levels 0 to 6) | about 3 million | 12.0 MB |
A multi-task (v0.7) model holds all four tasks, and one stage scores one of them: select it with setMode() before scoring, and copy the stage for every task you need, each with its own output column. A single-task (v0.6) model scores its own task and needs no setMode(). getClasses() returns the labels of the selected mode. In the model names, 3m, 870k and 850k give the rounded number of parameters; the fast variants are about 4 to 5 times faster per note (see the speed benchmark below).
What the models do
| Model | Scores | Use on | What it does | Example |
|---|---|---|---|---|
| PHI Guard v0.6 | 1: the probability that PHI is still readable | De-identified text | Gate de-identified notes before they leave the pipeline. | “Pt Maria Delgado seen on [DATE]…” scores 0.99 (leak); “Pt [NAME] seen on [DATE]…” scores 0.02 |
| PHI Guard v0.6 Fast | 1: the same score | De-identified text | The same gate when speed matters more than precision. It flags many more clean notes. | |
| PHI Guard Masked v0.6 | 1: the same score | De-identified text | The v0.6 gate with a final fine-tuning step. It scores almost the same as PHI Guard v0.6. | |
| PHI Guard Raw v0.6 | 1: the probability that a raw note holds any PHI | Raw text | Skip or route PHI-free notes before de-identification. | “Shortness of breath, lungs clear, continue inhaler.” scores 0.01; “John Miller, 64, seen 2024-02-11…” scores 0.99 |
| PHI Guard Richness v0.6 | 6: the probability that the level is at least 1, 2, up to 6; the level is how many reach 0.5 | Raw or de-identified text | How much PHI a note exposes, from level 0 (none) to level 6 (saturated). | A discharge note with a name, date of birth, MRN and phone number gets level 5 |
| PHI Guard v0.7 | 9: leak, harmful, richness (at least 1 to 6) and raw; a stage returns the scores of its mode | Both, depending on the mode | All four modes in one model. | “Patient [NAME], DOB 03/14/1956, MRN 4471923…” gets leak 0.99, harmful 0.99, richness level 3 and raw 0.10 |
| PHI Guard v0.7 Fast | The same 9 scores | Both, depending on the mode | The same modes, about 5x faster and a little less exact. |
PHI Guard v0.7 folds the leak, raw and richness models and a new harmful output into one model, with no loss of accuracy on any of them (see the benchmarks below).
Example: score a de-identified note and a note with a leak
document_assembler = DocumentAssembler() \
    .setInputCol("text") \
    .setOutputCol("document")

phi_leak = DecisionModel.pretrained("phi_guard_3m_v0.7", "en", "clinical/models") \
    .setMode("leak") \
    .setInputCols(["document"]) \
    .setOutputCol("phi_leak")
Result
+---------------------------------------------------------------------------+--------------+
|text                                                                       |label         |
+---------------------------------------------------------------------------+--------------+
|Example fictional note: Alex Rivera visited Riverside Clinic on 2024-01-15.|PHI_PRESENT   |
|Example fictional note: <NAME> visited <HOSPITAL> on <DATE>                |NO_PHI_PRESENT|
|Record date : <DATE> , <NAME> , M.D .                                      |NO_PHI_PRESENT|
|Call the clinic at (555) 123-4567 or email <CONTACT> .                     |PHI_PRESENT   |
|Paciente Juan Pérez , fecha de ingreso 12/05/2090 .                        |PHI_PRESENT   |
|Patient is a <AGE> year old male seen by Dr. <NAME> on <DATE> .            |NO_PHI_PRESENT|
|Phone (302) 786-5227, 0295 Keats Street, San Francisco.                    |PHI_PRESENT   |
|Name : Hendrickson, Ora, Record date: 2093-01-13, Age: 25, # 719435.       |PHI_PRESENT   |
|My name is <NAME> living in <LOCATION>.                                    |NO_PHI_PRESENT|
+---------------------------------------------------------------------------+--------------+
With phi_guard_3m_v0.6_richness, the same two notes get the levels NONE (level 0) and HIGH (level 4).
Example: find the notes that contain PHI
phi_guard = DecisionModel.pretrained("phi_guard_3m_v0.7", "en", "clinical/models")

phi_presence = phi_guard.copy() \
    .setMode("raw") \
    .setInputCols(["document"]) \
    .setOutputCol("phi_presence")

phi_presence.getClasses()
# ['PHI_PRESENT', 'NO_PHI_PRESENT']
Example: add a leak check to a de-identification pipeline also filter out leaked docs
The leak mode must score the de-identified document, so it reads the output column of the de-identification stage (here masked), not the original note:
deid_pipeline = PretrainedPipeline("clinical_deidentification_docwise_benchmark_optimized_v2", "en", "clinical/models")

phi_leak = phi_guard.copy() \
    .setMode("leak") \
    .setInputCols(["masked"]) \
    .setOutputCol("phi_leak")

doc_filterer = DocumentFiltererByClassifier() \
    .setInputCols(["masked", "phi_leak"]) \
    .setOutputCol("released_documents") \
    .setWhiteList(["NO_PHI_LEAK"]) \
    .setCaseSensitive(False) \
    .transform(scored)

deid_with_guard = PipelineModel(stages=list(deid_pipeline.model.stages) + [phi_leak + doc_filterer])
Good to know
- Long documents. PHI Guard reads a document in overlapping windows and combines them into one decision for the whole document;
n_windowsin the metadata tells how many windows were read. Documents up to 2,000,000 UTF-8 bytes are scored. - Check the
status. Every result carriesstatusin its metadata:scoredfor a model decision,emptyfor an empty document (a negative label without running the model;UNKNOWNinrichnessmode), andoverlengthfor a document above the size limit, which getsREVIEW_REQUIREDand no probability. Filter onstatus == "scored"before letting documents through on a negative label. - Choose your own cutoff. The labels use a cutoff of 0.5 on the probability. When your release process needs to catch nearly every leak, apply a lower cutoff to the probability in the metadata (e.g.
phi_leak_prob), chosen on validation data of your own; the benchmark below shows how precision and recall trade off. - Sentences or chunks. The input can also be sentences (
SentenceDetector) or chunks (InternalDocumentSplitter); each one then gets its own decision. Combining them into a decision for the whole note is a policy of your own. - A quality signal, not a certificate. A negative label is a strong signal that helps you decide where to look, not a privacy or release guarantee. Keep it next to your review process, not in place of it.
De-Identification Enhancements
These improvements apply across the de-identification family (DeIdentification, LightDeIdentification, StructuredDeidentification and the FHIR, CDA and HL7 v2 de-identification annotators).
Consistent fakes for possessive names
A name and its possessive form used to be obfuscated as two different words, so “Carter” and “Carter’s” could get two unrelated fakes, and the reader of the de-identified text would see two different people. Now the possessive marker ('s, ', ’s, ’) is separated from the name, the name is obfuscated as the name, and the marker is put back exactly as it was written:
Original:      Mr. Carter was admitted on Monday. Carter's daughter was informed.
De-identified: Mr. Ellison was admitted on Monday. Ellison's daughter was informed.
An apostrophe that belongs to the name (e.g. “O’Neil”) is not treated as a marker. The feature works with every name entity, with static obfuscation pairs, custom fakers, obfuscation equivalents and the name-part consistency options, and a masked name stays a plain mask.
Timestamps keep their time when dates are shifted
Date shifting now recognizes timestamps: the date part is shifted and the time, separator and time zone are kept exactly as they were written.
2024-03-04T10:30:00Z      + 5 days  ->  2024-03-09T10:30:00Z
3/4/2024 9:05 AM          + 5 days  ->  3/9/2024 9:05 AM
This covers ISO 8601 timestamps (as in FHIR dateTime and instant, with fractions of a second and time zone offsets) and a date followed by a space, a comma or “at” and a time, on a 12- or 24-hour clock.
Shift dates in both directions (setMinRandomDisplacementDays)
With setIsRandomDateDisplacement(True), dates used to move forward only, by 1 to maxRandomDisplacementDays days. The new minRandomDisplacementDays parameter sets the lower bound, which may be negative, so dates can move in both directions; 0 is never used. The default (1) keeps the previous behavior, and the outputs of existing pipelines do not change.
deid.setIsRandomDateDisplacement(True) \
    .setMinRandomDisplacementDays(-30) \
    .setMaxRandomDisplacementDays(30)
Configurable restricted ZIP code prefixes (setObfuscateZipRestrictedPrefixes)
Under HIPAA Safe Harbor, the first three digits of a ZIP code may be kept only when the area they cover has more than 20,000 people; otherwise they become 000. The embedded list is the 17 prefixes of the HHS guidance, based on 2000 Census data, and HHS notes that it should be updated when more current Census data is published. The list is now configurable, so you can use prefixes computed from current data:
deid.setObfuscateZipByHipaa(True) \
    .setObfuscateZipRestrictedPrefixes([
        "036", "059", "102", "202", "203", "204", "205", "369", "556",
        "692", "753", "772", "821", "823", "878", "879", "884", "893",
    ])  # e.g. computed from the 2020 Census
Safer handling of unusual ZIP values
With obfuscateZipByHipaa, a value that is not a plain 5- or 9-digit ZIP code is never replaced by a realistic fake ZIP code anymore. It keeps its first digits (zeros for a restricted prefix) and the rest is masked; a ZIP code that lost its leading zero gets it back first, and a value with letters is masked entirely:
2115          ->  021**
02115123456   ->  021********
K1A0B1        ->  ******
FHIR De-Identification for Real-World FHIR Data
FhirDeIdentification de-identifies FHIR resources and Bundles by rules. Real FHIR exports are more than a set of well-known fields: PHI sits in narratives and notes, in vendor extensions, in deeply nested elements, and in references that tie hundreds of resources to the same patient. This release extends FhirDeIdentification with what such data needs.
FHIR de-identification is part of the FHIR build of Healthcare NLP. Start it with
sparknlp_jsl.start(secret=SECRET, fhir_deid=True).
Free text inside resources
Narratives (text.div), notes (Observation.note.text, Annotation.text), descriptions and string values are now de-identified with a Healthcare NLP de-identification pipeline set via setPipeline():
setFreeTextPaths()selects free-text fields by path; a path without a resource type (e.g.text.div) applies to every resource, including Bundle entries and contained resources.setFreeTextDataTypes()selects free text by FHIR data type wherever it appears (e.g.Annotation.text,Extension.valueMarkdown).- XHTML narratives are de-identified node by node, so the markup survives; plain text and markdown are de-identified line by line, keeping list, heading and quote markers.
- With
setTableHandling(True)(default), every table cell is sent with its column header as context ("<header> : <cell value>"), so the model can tell a name from a date in a table; the header cells are then de-identified on their own, as they may hold PHI too. setExcludeFreeTextTags()skips the XHTML elements you name.
Rules that follow the data type, not just the path (setDataTypeRules)
Path rules (setMappingRules) work well for the fields you know. Data type rules catch the rest: a rule such as "HumanName.family": "LAST_NAME" or "dateTime": "DATE" applies wherever that type appears — in any resource, at any depth, inside extensions, in contained resources and in Bundle entries. Every value is de-identified only once, and a path rule always takes precedence over a data type rule.
Remove, keep or pseudonymize: new rule actions
| Rule value | What it does |
|---|---|
REMOVE |
Removes the matched elements, primitive or complex (e.g. Patient.photo, meta.source, an extension). A resource type alone (e.g. "AuditEvent": "REMOVE") drops every resource of that type and every reference to one. |
REMOVE_BASE64 |
Removes only the values that are embedded files (base64 payloads of more than 100 characters) and keeps the other values at the same path. |
KEEP |
Keeps the matched values as they are, e.g. "Immunization.expirationDate": "KEEP" keeps vaccine expiration dates while a date data type rule shifts every other date. |
LOCAL_CODING |
Keeps standard code systems (LOINC, SNOMED CT, ICD, RxNorm, HL7 terminologies, …) as they are and replaces local code systems with a consistent pseudonym (urn:oid:2.25.<number>); local display texts go to the free-text pipeline. |
LOCAL_URI |
Applies the same logic to uri, url, oid, uuid and canonical values. |
Every rule can select elements by the value of a child with where(child='value'), e.g. "Patient.telecom.where(system='email')": "REMOVE" removes the email addresses of a patient and leaves the phone numbers to the other rules. After the rules, extensions left without a value are removed, so the output stays valid FHIR (invariant ext-1).
One date shift per patient
With setIsRandomDateDisplacement(True), all dates of a patient move by the same number of days — in every resource, in every document and in every run with the same seed — so intervals between events are preserved. The patient of each resource is found from its references, its container or the Patient of the document, and getDateShiftForPatient() returns the offset. When the documents of one subject hold several Patient records or resources without a patient, deidentify_list(documents, ids, date_shift_keys) shifts every document of the subject by one offset. Free text gets the same offset when the free-text pipeline uses DocumentHashCoder and setUseShiftDays(True). Partial dates (2020, 2020-03) are shifted and kept at their original precision, and placeholder dates such as 0001-01-01 are kept as they are.
HIPAA age and birth date rules
setAgeReferenceDate()applies the 90+ rule: a birth date that makes the person 90 or older at the reference date becomes the year that makes them 90, so all these patients fall into one group while the output stays a valid date.setDateToYearEntities(["DOB"])keeps birth dates as years only, while every other date is shifted.setBirthYearDatesToYear(True)writes the dates that fall in a newborn’s birth year as that year, so that a shifted test date cannot narrow down the birth date.
Identifiers and references stay consistent
UUID ids become valid, consistent pseudonymous UUIDs, and references follow them, so the links between resources survive de-identification. setPatientIdentifierSystem() adds one pseudonymous identifier to every Patient. Name titles (Dr.) and prefixes such as tel:, mailto: and urn:uuid: are kept while the value behind them is de-identified.
Real-world data that is not perfectly valid (setErrorOnInvalidValue)
Exports often contain values that strict FHIR parsing rejects, such as codes in the wrong case ("PHONE" instead of "phone"). With setErrorOnInvalidValue(False) these codes are repaired and other invalid values are kept and still de-identified, instead of the whole document failing. In deidentify_list, a document that cannot be de-identified does not stop the others: its output is None, and the error is logged. Invalid values are never written to the application log, as they may be PHI.
Audit logs and traceability tags
setEnableOutputLogs(True)andsetOutputLogsPath()(local, HDFS, DBFS or S3) write a summary per run with counts by entity, action, rule, resource type and free-text field — without any original value. WithsetReturnEntityMappings(True), a detailed record per de-identified value and document is written too; it holds the original values, so keep it apart from the de-identified data, with restricted access.setOutputMetaTags()adds your own tags (e.g. a project or release name) tometa.tagof every output document, andsetAddProcessingMetaTags(True)adds the Healthcare NLP version and the processing time.
Extract free text for annotation (extract_free_text)
extract_free_text() and extract_free_text_list() return the free text of documents split exactly as the pipeline receives it — narrative nodes, table cells with their headers, lines — with the resource, path and position of every segment, without de-identifying it. This makes it easy to annotate your own data, train or fine-tune the NER models of the free-text pipeline (see Annotation2Training below), and evaluate them on the texts they will really see. The same methods are available in CdaDeIdentification and Hl7v2DeIdentification.
Throughput
deidentify_list() processes documents in parallel and keeps their order; the free-text parts of a document are sent to the pipeline in parallel (setParallelFreeText, on by default), and setFreeTextCacheSize() reuses the result of texts that repeat across documents.
Example
import sparknlp_jsl
from sparknlp.pretrained import PretrainedPipeline
from sparknlp_jsl.annotator import FhirDeIdentification

spark = sparknlp_jsl.start(secret=SECRET, fhir_deid=True)

free_text_pipeline = PretrainedPipeline(
    "clinical_deidentification_docwise_benchmark_optimized_v2", "en", "clinical/models"
)

fhir_deid = FhirDeIdentification() \
    .setFhirVersion("R4") \
    .setParserType("JSON") \
    .setMode("obfuscate") \
    .setSeed(2024) \
    .setMappingRules({
        "Patient.birthDate": "DOB",
        "Patient.photo": "REMOVE",
        "Patient.telecom.where(system='email')": "REMOVE",
        "AuditEvent": "REMOVE",
        "Immunization.expirationDate": "KEEP",
    }) \
    .setDataTypeRules({
        "date": "DATE",
        "dateTime": "DATE",
        "HumanName.family": "LAST_NAME",
        "HumanName.given": "FIRST_NAME",
        "Address.line": "STREET",
        "Address.city": "CITY",
        "Address.postalCode": "ZIP",
        "Identifier.value": "ID",
    }) \
    .setIsRandomDateDisplacement(True) \
    .setMinRandomDisplacementDays(-30) \
    .setMaxRandomDisplacementDays(30) \
    .setAgeReferenceDate("2026-06-30") \
    .setObfuscateZipByHipaa(True) \
    .setFreeTextPaths(["text.div", "DiagnosticReport.conclusion", "Condition.note.text"]) \
    .setFreeTextDataTypes(["Extension.valueMarkdown"]) \
    .setPipeline(spark, free_text_pipeline, "obfuscated") \
    .setEnableOutputLogs(True) \
    .setOutputLogsPath("s3://my-bucket/fhir-deid/logs/") \
    .setOutputMetaTags({"project": "readmission_study", "release": "r3"})

deidentified = fhir_deid.deidentify_list(fhir_documents, ids=file_names)
Free text is de-identified by
deidentify()anddeidentify_list(), which run the pipeline on the driver.transform()keeps working for structured rules, and fails with a clear message when free-text paths are set.
CDA and HL7 v2 De-Identification Improvements
CdaDeIdentification and Hl7v2DeIdentification share the new rule engine with FHIR, so most of the options above work for them too:
- Header-aware tables in CDA narratives. Header cells give their column as context to the data cells, a table without a header row uses its first row as the header (and still de-identifies it), and the header cells are then de-identified on their own, as they may hold PHI too.
- CDA contact values resolved from their shape. A telecom value is de-identified as a phone or an email depending on its content, and URI schemes such as
tel:andmailto:are kept. REMOVEandREMOVE_BASE64.REMOVEclears the value of the matched node or field, andREMOVE_BASE64clears only embedded base64 payloads.- Year-only dates and age rules.
setDateToYear,setDateToYearEntitiesandsetAgeReferenceDatenow apply to CDA and HL7 v2 as well. - Random date shift range.
setMinRandomDisplacementDaysandsetMaxRandomDisplacementDayswork as in the other de-identification annotators. - Possessive names keep their marker on the fake in HL7 v2 messages as well.
- Free-text extraction with
extract_free_text()/extract_free_text_list()returns the narrative texts and free-text fields as the pipeline receives them. - Document-level logs with
setEnableOutputLogs(True).
Keep the Annotated Chunks When Converting Generative AI Lab Exports to NER Training Data
Annotation2Training converts Generative AI Lab exports (JSON and CSV) into a DataFrame ready for MedicalNerApproach. The annotations were turned into token-level IOB labels and the original entity spans were then dropped, so they could not be checked against the labels or reused for evaluation.
convertJson2NerDF and convertCsv2NerDF now accept chunk_output_col. When it is set, the annotated chunks are kept in the result as a regular Spark NLP chunk column, with white_list, black_list and replace_labels already applied:
from sparknlp_jsl.training import Annotation2Training

annotation2training = Annotation2Training(spark)

training_df = annotation2training.convertJson2NerDF(
    json_path="path/to/annotations.json",
    pipeline_model=pipeline_model,          # DocumentAssembler + SentenceDetector + Tokenizer
    white_list=["Drug", "Heart_Failure", "Cardiac_Arrythmia"],
    replace_labels={"Cardiac_Arrythmia": "Condition"},
    chunk_output_col="ner_chunk",           # new: keep the annotated chunks
)

training_df.columns
# ['text', 'id', 'document', 'sentence', 'token', 'label', 'ner_chunk']
This makes it easy to compare the annotations with the generated IOB labels, compute entity statistics of a training set, or keep the gold chunks for a later evaluation. The parameter is off by default, so existing scripts return the same columns as before, and a name that clashes with an existing column is rejected instead of overwriting it.
PipelineTracer Supports PretrainedZeroShotMultiTask and MultiAnnotationSplitter
PipelineTracer reports which entities, relations and assertions a pipeline can produce, and in which output columns. It now understands PretrainedZeroShotMultiTask and follows its output through MultiAnnotationSplitter:
from sparknlp_jsl.pipeline_tracer import PipelineTracer

multi_task = PretrainedZeroShotMultiTask.pretrained("zeroshot_multitask_base", "en", "clinical/models") \
    .setInputCols(["document"]) \
    .setOutputCol("extractions") \
    .setEntities(["person", "company::str", "price::str::Monetary value including currency"]) \
    .setRelations(["works_for", "located_in::The organization is physically located in the place"])

chunk_splitter = MultiAnnotationSplitter() \
    .setInputCols(["extractions"]) \
    .setOutputCol("ner_chunk") \
    .setSplitType("chunk")

model = Pipeline(stages=[document_assembler, multi_task, chunk_splitter]) \
    .fit(spark.createDataFrame([[""]]).toDF("text"))

tracer = PipelineTracer(model)

tracer.getPossibleEntities()
# ['person', 'company', 'price']

tracer.getPossibleRelations()
# ['works_for', 'located_in']

tracer.createParserDictionary()["entities"]
# ['ner_chunk']
The tracer reports clean names — data types and descriptions in the entity and relation specs never appear as labels — and narrows them when a later stage filters the chunks, e.g. a ChunkFilterer with a white list. It only reads the stage parameters and never runs the model, so tracing stays fast even for large pipelines.
Faster Pretrained Model Downloads
Healthcare NLP 7.0.1 is built on Spark NLP 7.0.1, which downloads pretrained models and pipelines in parallel: a model is fetched over several connections at once instead of a single one, which shortens the wait for large models such as embeddings and de-identification pipelines. The download now also shows byte-accurate progress (percentage and MB) instead of a spinner: a progress bar in a terminal, and one line per percent in notebooks, CI logs and redirected output. Licensed Healthcare NLP models use the same mechanism.
The behavior can be tuned with Spark configuration:
| Setting | Default | Description |
|---|---|---|
spark.jsl.settings.pretrained.download_threads |
10 |
Maximum number of parallel connections per download; 1 restores the single-connection download |
spark.jsl.settings.pretrained.download_progress |
auto |
bar, lines or off; auto picks bar in a terminal and lines elsewhere |
spark.jsl.settings.pretrained.s3_socket_timeout |
900000 (15 min) |
How long, in milliseconds, a download may wait for the next bytes before it fails; not a cap on the total download time |
spark = sparknlp_jsl.start(secret=SECRET, params={
    "spark.jsl.settings.pretrained.download_threads": "16",
})
Bug Fixes & Stability Improvements
- FHIR
transformafterdeidentify. Callingtransformon an instance that had already rundeidentifyfailed with aTask not serializableerror; both now work on the same instance. - FHIR choice-type paths. A rule on a choice-type element (e.g.
Observation.valueCodeableConcept.text) no longer fails the documents in which the element has another type (e.g.valueQuantity). - Rule precedence. A path rule now always takes precedence over a data type
REMOVErule for the same value. - Nested narrative tables. Rows of nested tables in XHTML and CDA narratives are no longer processed twice, which used to shift their dates twice.
- Placeholder dates. Dates of the year 1 (e.g.
0001-01-01), used by some systems as placeholders, are kept instead of being shifted into invalid dates.
PHI Guard Benchmarks: Leak, Harmful Leak, Raw Note, Richness and Speed
The PHI Guard family has seven models. Each answers one or more questions about a note: does a de-identified note still leak PHI (leak), does a raw note hold any PHI (raw), how much PHI does a note expose (richness), and is a leak harmful (harmful). The results below compare them on each question; the model names map to the pretrained models as listed in the DecisionModel section above. Medical DM Small, a larger John Snow Labs decision model that runs on a GPU and is offered separately from the Healthcare NLP library, is included as a reference.
PHI Leak Detection
Does a de-identified note still leak PHI? PR-AUC with a leak as the positive class. Public sets are the mean of four public datasets. The last column counts clean notes wrongly flagged at the 0.5 cut-off on the main set; fewer is better. Bold is the best in each column.
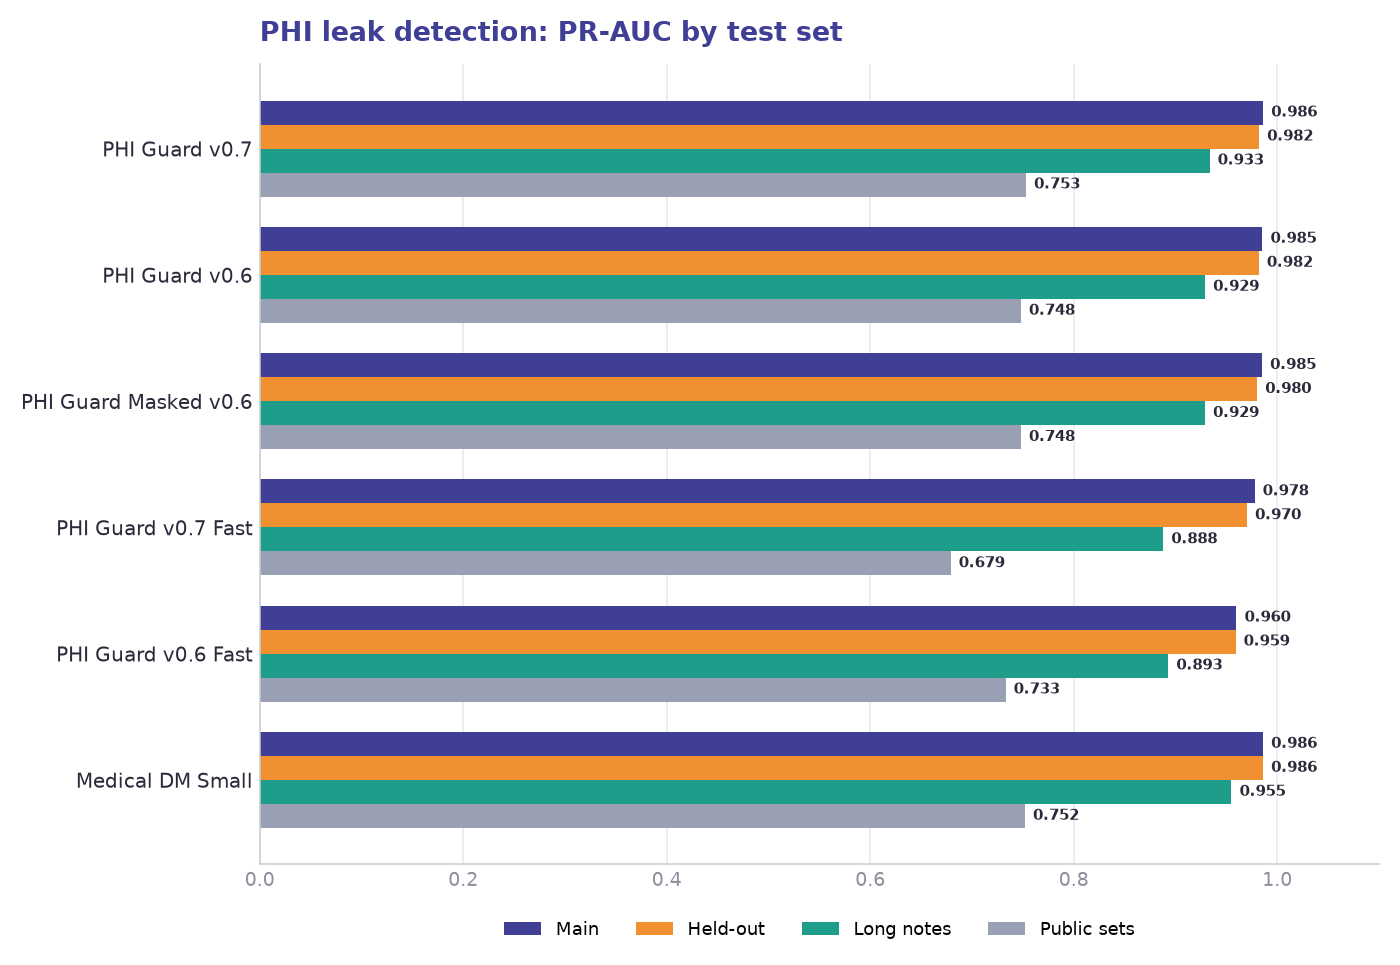
| Model | Main | Held-out | Long notes | Public sets | Clean notes flagged, main |
|---|---|---|---|---|---|
| PHI Guard v0.7 | 0.986 | 0.982 | 0.933 | 0.753 | 91 |
| PHI Guard v0.6 | 0.985 | 0.982 | 0.929 | 0.748 | 91 |
| PHI Guard Masked v0.6 | 0.985 | 0.980 | 0.929 | 0.748 | 96 |
| PHI Guard v0.7 Fast | 0.978 | 0.970 | 0.888 | 0.679 | 113 |
| PHI Guard v0.6 Fast | 0.960 | 0.959 | 0.893 | 0.733 | 384 |
| Medical DM Small | 0.986 | 0.986 | 0.955 | 0.752 | 39 |
PHI Guard v0.7 matches or slightly beats PHI Guard v0.6 on every set. PHI Guard v0.7 Fast has far fewer false alarms than PHI Guard v0.6 Fast on the main set (113 against 384), but it is weaker on the public sets (0.679 against 0.733).
Harmful Leaks
Harmful PR-AUC, and the share of harmless-only leaks wrongly flagged at 0.5 on the main set; lower is better. The v0.6 models have no harmful mode, so the v0.6 leak score stands in.
| Model | Main | Held-out | Long notes | Harmless-only leaks flagged, main |
|---|---|---|---|---|
| PHI Guard v0.6 (leak score) | 0.962 | 0.779 | 0.904 | 70% |
| PHI Guard v0.7 | 0.980 | 0.883 | 0.928 | 38% |
| PHI Guard v0.7 Fast | 0.977 | 0.885 | 0.936 | 21% |
Raw Notes
Does a raw note contain any PHI? PR-AUC on the test split and on held-out notes, and the notes wrongly flagged or missed at 0.5 on the test split.
| Model | Test PR-AUC | False positives | False negatives | Held-out PR-AUC |
|---|---|---|---|---|
| PHI Guard Raw v0.6 | 0.9993 | 29 | 38 | 0.9984 |
| PHI Guard v0.7 | 0.9992 | 28 | 42 | 0.9986 |
| PHI Guard v0.7 Fast | 0.9993 | 47 | 42 | 0.9973 |
Richness
How much PHI a note exposes. Level error (MAE, lower is better) and rank correlation (rho, higher is better) on masked notes; the last two columns are held-out raw notes.
| Model | Main MAE | Main rho | Held-out MAE | Held-out rho | Long MAE | Long rho | Raw MAE | Raw rho |
|---|---|---|---|---|---|---|---|---|
| PHI Guard Richness v0.6 | 0.137 | 0.859 | 0.325 | 0.902 | 0.245 | 0.773 | 0.265 | 0.954 |
| PHI Guard v0.7 | 0.140 | 0.866 | 0.303 | 0.909 | 0.238 | 0.755 | 0.238 | 0.956 |
| PHI Guard v0.7 Fast | 0.162 | 0.850 | 0.372 | 0.894 | 0.271 | 0.715 | 0.301 | 0.949 |
Speed per Note
CPU models: one thread, a 1 KB note. GPU model: batched on a 24 GB GPU.
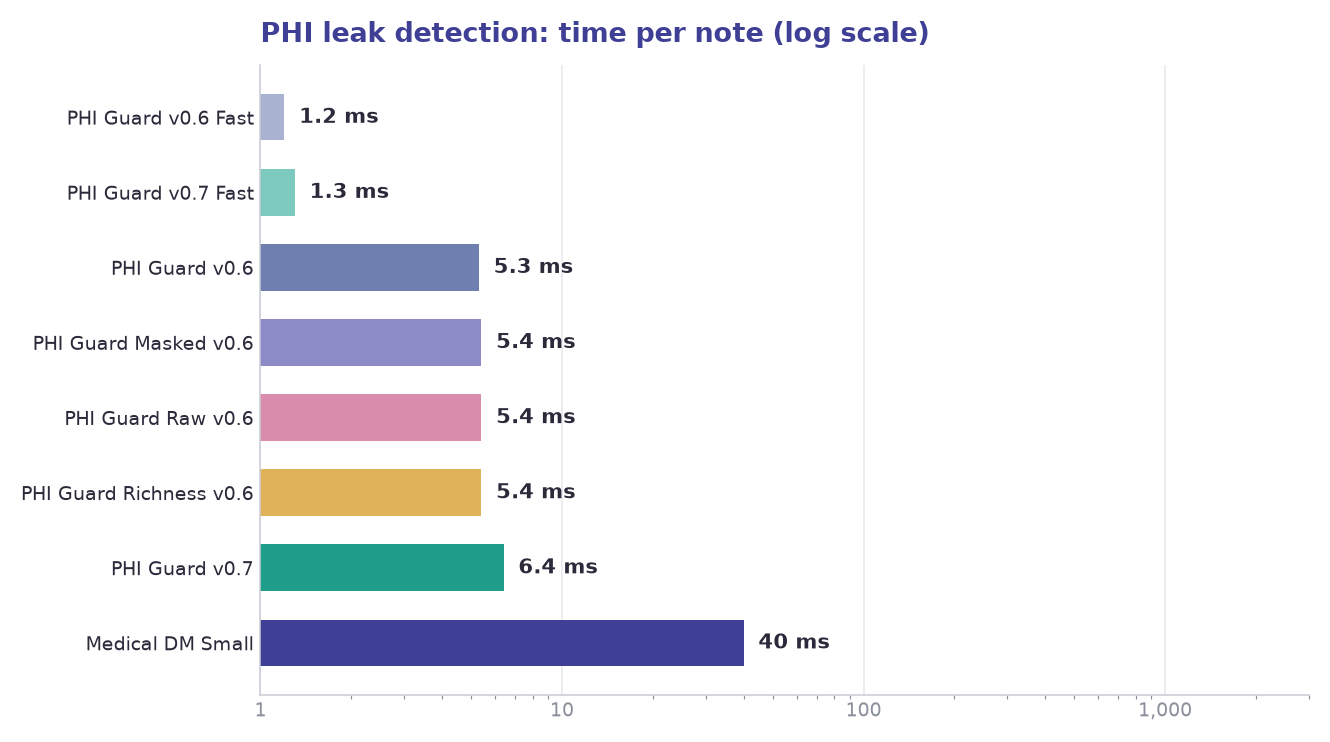
| Model | Runs on | Per note (ms) | One million notes |
|---|---|---|---|
| PHI Guard v0.6 | CPU, one thread (ONNX) | 5.3 | 1.5 h |
| PHI Guard v0.6 Fast | CPU, one thread (ONNX) | 1.2 | 20 min |
| PHI Guard Masked v0.6 | CPU, one thread (ONNX) | 5.4 | 1.5 h |
| PHI Guard Raw v0.6 | CPU, one thread (ONNX) | 5.4 | 1.5 h |
| PHI Guard Richness v0.6 | CPU, one thread (ONNX) | 5.4 | 1.5 h |
| PHI Guard v0.7 | CPU, one thread (ONNX) | 6.4 | 1.8 h |
| PHI Guard v0.7 Fast | CPU, one thread (ONNX) | 1.3 | 21.7 min |
| Medical DM Small | GPU (24 GB) | 40 | ~10-12 h |
The timings are for one CPU thread. In a Spark pipeline, DecisionModel scores the partitions of a DataFrame in parallel, so a cluster scores many notes at the same time.
PHI Guard v0.6 on the Public MedDeID Synthetic Benchmark
How reliably does PHI Guard spot a de-identified note that still carries PHI? The leak mode of PHI Guard v0.6 and PHI Guard v0.6 Fast was evaluated on the test split of the public MedDeID English synthetic benchmark (CC BY 4.0, revision 288c5718e5112e75c857ddf511a30e6eb6b32cdb). Its 300 source notes give 600 examples: in 300 of them every PHI span is masked (clean notes), in the other 300 exactly one PHI span is left in (a single leak) — the hard case of one leaked value in an otherwise fully masked note. The notes were scored through the saved DecisionModel Spark stage, whose probabilities matched the reference ONNX scoring within 2.2e-7.
A quality gate has to catch nearly every leak, so the results are reported at a fixed recall: at the cutoff that catches 95% or 98% of the leaks, how precise the flags are, and how many clean notes are flagged for review (false alarms).
| Model | Precision at 95% recall | Precision at 98% recall | False alarms at 98% recall (of 300 clean notes) |
|---|---|---|---|
PHI Guard v0.6 (phi_guard_3m_v0.6) |
0.743 | 0.649 | 159 |
PHI Guard v0.6 Fast (phi_guard_850k_v0.6_fast) |
0.604 | 0.546 | 244 |
At 98% recall, PHI Guard v0.6 catches 294 of the 300 leaks and flags 159 of the 300 clean notes for review; PHI Guard v0.6 Fast reaches the same recall with 244 false alarms.
| Model | Target recall | Precision | Achieved recall | TP | FP | FN | TN | Cutoff |
|---|---|---|---|---|---|---|---|---|
| PHI Guard v0.6 | 95% | 0.743 | 0.953 | 286 | 99 | 14 | 201 | 0.033407 |
| PHI Guard v0.6 | 98% | 0.649 | 0.980 | 294 | 159 | 6 | 141 | 0.009149 |
| PHI Guard v0.6 Fast | 95% | 0.604 | 0.950 | 285 | 187 | 15 | 113 | 0.079184 |
| PHI Guard v0.6 Fast | 98% | 0.546 | 0.980 | 294 | 244 | 6 | 56 | 0.040668 |
The masking in this benchmark is idealized: the gold PHI spans were masked directly, without running NER or a de-identification pipeline, so results on the output of a real pipeline will differ. The cutoffs were chosen on this test set after scoring; they illustrate the trade-off and are not recommended thresholds. Choose yours on validation data of your own.
Medical Decision Models (DMs): Task Benchmark Performance and Cost
PHI Guard is one family of John Snow Labs’ Medical Decision Models (DMs): compact models that answer typed questions about clinical text, such as whether a note documents a condition, whether a drug caused an event, or whether a trial accepts a patient. A question can ask the model to pick one option, answer yes or no with a probability, or choose an ordered level. Medical DMs are small enough to deploy privately, and the smallest run on a CPU. The question and its options are part of the input, so a new rule or a new threshold needs no retraining.
Medical DM Small is the best-scoring decision model across nine medical task areas, and Medical DM Nano is the compact option that runs on a single small GPU or on CPU. Both are offered for private deployment (On-Premise, AWS, Azure, Databricks, Snowflake), separately from the Healthcare NLP library.
| Model Name | Best for | Runs on | Recommended Memory | Max Sequence Length | Supported Platforms |
|---|---|---|---|---|---|
| Medical DM Small | Highest average score across the nine task areas | GPU | ~16 GB GPU VRAM | 16K | On-Premise, AWS, Azure, Databricks, Snowflake |
| Medical DM Nano | Compact; runs on a single small GPU or on CPU | GPU or CPU | ~2 GB GPU VRAM | 16K | On-Premise, AWS, Azure, Databricks, Snowflake |
Note: Recommended memory assumes half-precision (bf16) weights plus working memory at the maximum sequence length.
Tasks covered
| Task area | What the model decides |
|---|---|
| Cancer registry abstraction | Registry fields from a pathology report: organ, tumor type, grade, TNM categories, stage, margins, lymphovascular invasion, receptors. A field the report never states is returned as not stated. |
| Coding and prior authorization | Whether a diagnosis or a prior-authorization request is supported under a rule written into the question. |
| Cohort identification | Whether a patient has each condition on a list: present, possible, absent or not documented. |
| Adverse drug events | For one drug and one event: onset, severity, attribution, action taken, and the outcome of stopping and restarting the drug. |
| General clinical decisions | A set of clinical decision tasks: evidence sufficiency, reconciliation, temporal relevance, reliability, attribution, escalation, causality, trajectory and more. |
| Quality measure review | Evidence questions on patient charts for adult care-quality measures: eligibility, exclusions, time windows, medicines and tests. |
| Clinical note review | Chart review of a clinical note: note type, age group, tobacco use, allergies, diabetes, kidney function, anticoagulation, cancer status. |
| Clinical trial eligibility | Demographic gate, inclusion or exclusion, specialty, numeric thresholds and time windows. |
| Oncology record review | Whether a document in an oncology record is relevant to a registry abstract, whether it adds anything new, and which fields it states. |
| PHI leak detection | Whether a de-identified note still leaks protected health information (PHI), whether a raw note holds any, how much a note exposes, and whether a leak is harmful. |
Task Benchmark Performance
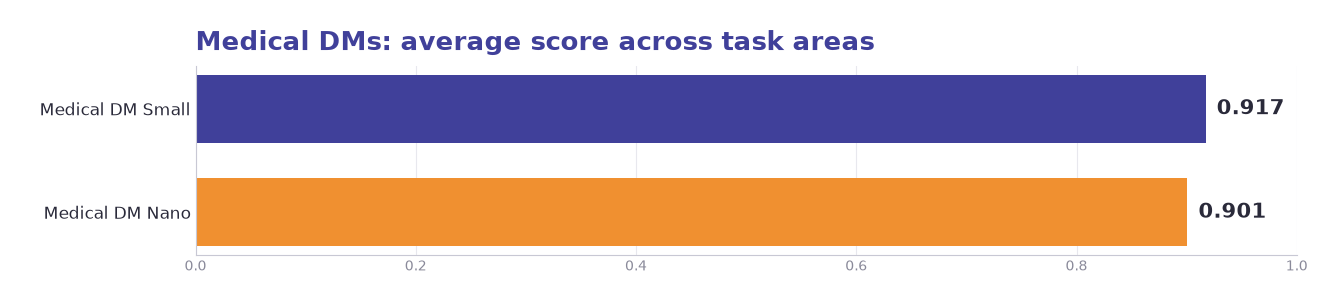
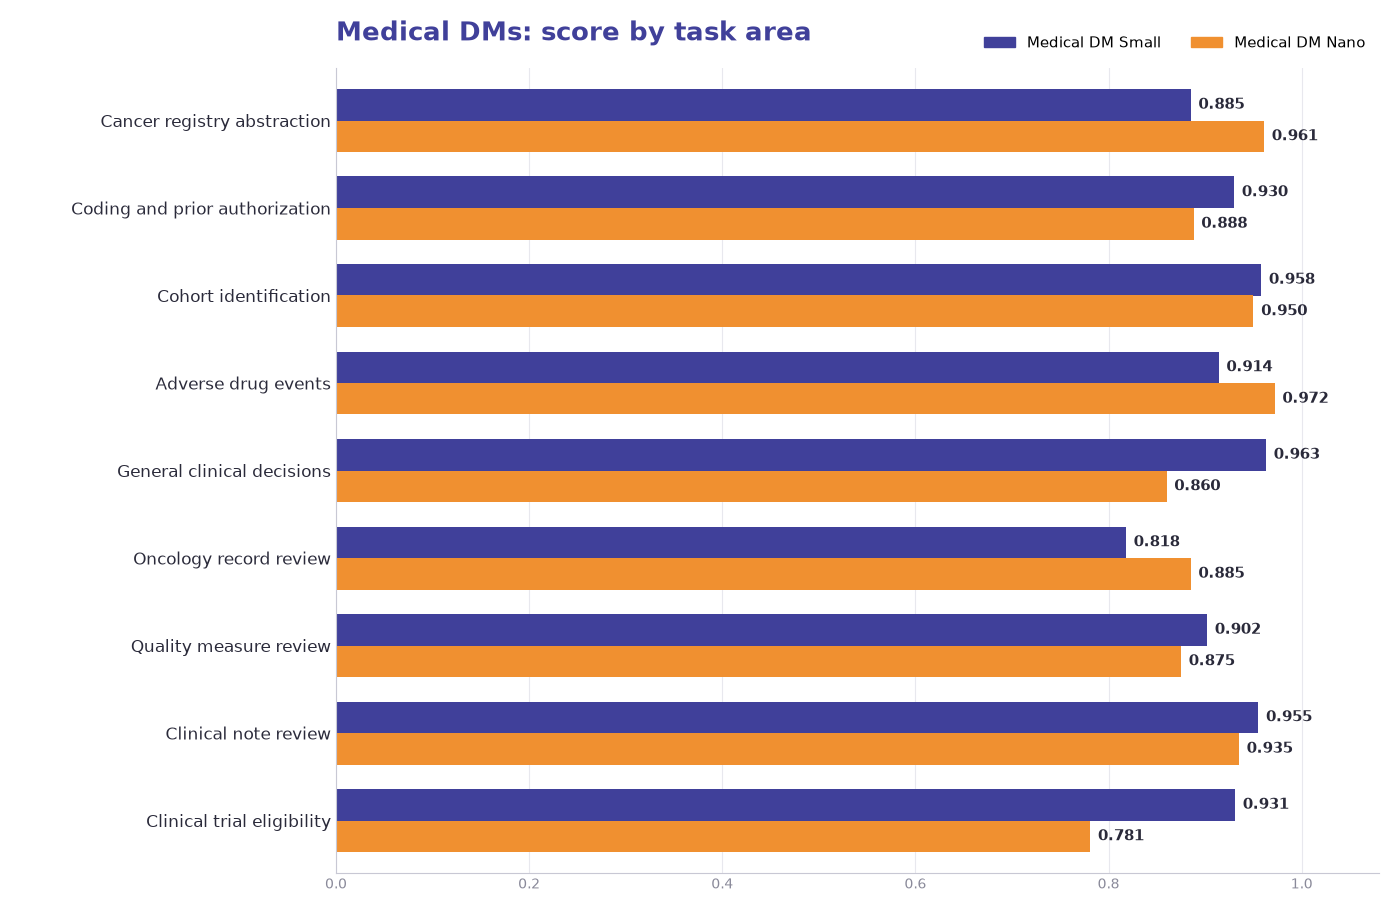
Score on nine task areas: the mean of accuracy and macro precision, recall and F1. Bold is the best score in the row.
| Task area | Medical DM Nano | Medical DM Small |
|---|---|---|
| Cancer registry abstraction | 0.961 | 0.885 |
| Coding and prior authorization | 0.888 | 0.930 |
| Cohort identification | 0.950 | 0.958 |
| Adverse drug events | 0.972 | 0.914 |
| General clinical decisions | 0.860 | 0.963 |
| Oncology record review | 0.885 | 0.818 |
| Quality measure review | 0.875 | 0.902 |
| Clinical note review | 0.935 | 0.955 |
| Clinical trial eligibility | 0.781 | 0.931 |
| Average | 0.901 | 0.917 |
Medical DM Small is ahead on six of nine task areas, with its largest margin on clinical trial eligibility (0.931 against 0.781). Medical DM Nano is ahead on cancer registry abstraction, adverse drug events and oncology record review.
Cost Analysis
In addition to processing speed, infrastructure cost is an important consideration when evaluating the operational scalability of Medical Decision Models. Based on our benchmark measurements, Medical DM Small processes approximately 40 ms per note, corresponding to an estimated 10–12 hours to process 1 million clinical notes on a GPU with 24 GB memory.
| Metric | Medical DM Small |
|---|---|
| Hardware | GPU (24 GB) |
| Processing time per note | 40 ms |
| Runtime per 1 million notes | ~10–12 hours |
| Assumed GPU cost per hour | $1.30 |
| Estimated cost per 1 million notes | $13.00–$15.60 |
Assuming linear scaling of processing time and compute costs:
| Number of notes | Estimated runtime | Estimated compute cost |
|---|---|---|
| 100,000 | 1–1.2 hours | $1.30–$1.56 |
| 1 million | 10–12 hours | $13.00–$15.60 |
| 10 million | 100–120 hours | $130.00–$156.00 |
| 100 million | 1,000–1,200 hours | $1,300.00–$1,560.00 |
The estimated compute cost is calculated as Runtime (hours) × GPU hourly rate. These estimates represent GPU compute costs only and exclude storage, networking, orchestration, and other infrastructure expenses. Actual costs will vary depending on the GPU instance, cloud provider, and deployment configuration.
The GPU hourly rate of $1.30 is an illustrative pricing assumption and is not an official John Snow Labs price. Runtime and cost estimates are based on the benchmark configuration described above. For comparison, the PHI Guard models in Healthcare NLP run on CPU, at 1.2 to 6.4 ms per note on one thread.
New Blog Posts & Technical Deep Dives
- John Snow Labs introduces three Medical Decision Model families for clinical text: Introduces Medical DM Small, Medical DM Nano and PHI Guard, compact models that answer typed questions about clinical text with probabilities. Medical DM Small averages 0.917 across nine task areas on a 16 GB GPU, Medical DM Nano averages 0.901 in about 2 GB on a GPU or CPU, and PHI Guard checks a 1 KB de-identified note in 6.4 ms on one CPU thread.
- PHI Guard finds leftover PHI in de-identified notes at 0.986 PR-AUC: Covers the seven CPU PHI Guard models that score de-identified notes for leftover and harmful PHI leaks and PHI exposure, and raw notes for PHI presence. The all-in-one
phi_guard_3m_v0.7reaches 0.986 PR-AUC for leak detection and checks a 1 KB note in 6.4 ms on one CPU thread; the fast variants are about five times faster. - De-identification Doesn’t End at Deployment: How to Know What Is Safe to Release: This post describes how to keep measuring a de-identification pipeline after deployment with drift checks on every new batch, PHI Guard screening of every output document, and a random audit that gives a bound on the leak rate. On notes written after the models were trained, the share of leaks caught fell from 93% to 84% and false alarms rose from 13% to 33%. A general judge model caught 5% of real leaks against 79% to 86% for purpose-built document classifiers, and 299 clean random documents support a 95% confidence claim that fewer than 1% of a release leaks.
- Why Mapping Clinical Notes to ICD-10, CPT, LOINC, and SNOMED Codes Takes More than Entity Recognition: This post explains why code mapping depends on assertion status, experiencer attribution and temporal anchoring, and how Healthcare NLP extracts entities and applies assertion detection before the Terminology Server maps them to ICD-10, CPT, LOINC or SNOMED CT. It cites a CPT coding study (Pandian et al., 2025) in which a model trained at one hospital reached 92.5% accuracy on its own data and lost about 22.4 points at another hospital, and an assertion comparison (Kocaman et al., 2025) in which the John Snow Labs clinical model reached 0.962 combined accuracy against 0.901 for GPT-4o.
Updated Notebooks And Demonstrations For Making Healthcare NLP Easier To Navigate And Understand
- New DecisionModel Notebook
This notebook covers the
DecisionModelannotator and the PHI Guard models for checking clinical documents for PHI. It includes scoring original notes for PHI presence, selecting theraw,leak,harmfulandrichnesstasks ofphi_guard_3m_v0.7, adding a leak check to a document-wise de-identification pipeline, and filtering de-identified documents by their PHI Guard label before release.
We Have Added And Updated A Substantial Number Of New Clinical Models And Pipelines, Further Solidifying Our Offering In The Healthcare Domain.
phi_guard_3m_v0.7phi_guard_870k_v0.7_fastphi_guard_3m_v0.6phi_guard_3m_v0.6_maskedphi_guard_850k_v0.6_fastphi_guard_3m_v0.6_rawphi_guard_3m_v0.6_richness
Previous versions
- 7.0.1
- 7.0.0
- 6.4.1
- 6.4.0
- 6.3.0
- 6.2.2
- 6.2.1
- 6.2.0
- 6.1.1
- 6.1.0
- 6.0.4
- 6.0.3
- 6.0.2
- 6.0.1
- 6.0.0
- 5.5.3
- 5.5.2
- 5.5.1
- 5.5.0
- 5.4.1
- 5.4.0
- 5.3.3
- 5.3.2
- 5.3.1
- 5.3.0
- 5.2.1
- 5.2.0
- 5.1.4
- 5.1.3
- 5.1.2
- 5.1.1
- 5.1.0
- 5.0.2
- 5.0.1
- 5.0.0
- 4.4.4
- 4.4.3
- 4.4.2
- 4.4.1
- 4.4.0
- 4.3.2
- 4.3.1
- 4.3.0
- 4.2.8
- 4.2.4
- 4.2.3
- 4.2.2
- 4.2.1
- 4.2.0
- 4.1.0
- 4.0.2
- 4.0.0
- 3.5.3
- 3.5.2
- 3.5.1
- 3.5.0
- 3.4.2
- 3.4.1
- 3.4.0
- 3.3.4
- 3.3.2
- 3.3.1
- 3.3.0
- 3.2.3
- 3.2.2
- 3.2.1
- 3.2.0
- 3.1.3
- 3.1.2
- 3.1.1
- 3.1.0
- 3.0.3
- 3.0.2
- 3.0.1
- 3.0.0
- 2.7.6
- 2.7.5
- 2.7.4
- 2.7.3
- 2.7.2
- 2.7.1
- 2.7.0
- 2.6.2
- 2.6.0
- 2.5.5
- 2.5.3
- 2.5.2
- 2.5.0
- 2.4.6
- 2.4.5
- 2.4.2
- 2.4.1
- 2.4.0