There is overwhelming evidence from both academic research and industry benchmarks that domain-specific, task-optimized large language models consistently outperform general-purpose LLMs in healthcare. At John Snow Labs, we’ve developed a focused pair of Medical LLMs purpose-built for clinical, biomedical, and life sciences applications.
Medical LLM Medium and Medical LLM Small are healthcare models benchmarked head-to-head against the leading closed frontier systems — GPT 5.5, Claude Opus 4.8, and Gemini 3.5 Flash — across the full spectrum of medical evaluation. Both are multimodal (text + image) and carry a locked John Snow Labs identity. Closed frontier models can’t run on your data — ours can: licensed for on-premise or private-cloud deployment, HIPAA-friendly, without giving up frontier-grade medical accuracy.
Our models are designed to deliver best-in-class performance across a wide range of medical tasks—from clinical reasoning and diagnostics to medical research comprehension and genetic analysis.
Medical LLMs Offering
| Model Name | Recommended GPU Memory | Max Sequence Length | Max KV-Cache | Tensor Parallel Sizes | Supported Platforms |
|---|---|---|---|---|---|
| Medical LLM Medium | ~67 GB | 262K | 16 GB | 2, 4, 8 | On-Premise AWS Azure Databricks Snowflake |
| Medical LLM Small | ~25 GB | 262K | 8 GB | 1, 2, 4, 8 | On-Premise AWS Azure Databricks Snowflake |
Note: All memory calculations are based on half-precision (fp16/bf16) weights. Recommended GPU Memory considers the model size and the maximum key-value cache at the model’s maximum sequence length. These calculations follow the guidelines from DJL’s LMI Deployment Guide.
- Medical LLM Small — Compact. A compact medical LLM that outperforms much larger general models on MedHELM while running on a single commodity GPU.
- Medical LLM Medium — Flagship. Our best model — the #1 MedHELM mean win rate in this comparison, leading frontier closed models on OpenMed.
Medical Small LLMs
John Snow Labs offers a curated portfolio of specialized small language models (1B-10B parameters), alongside larger, more capable models. Designed for real-world deployment, these models are quantized for efficiency and can run on standard CPU-based hardware without requiring a GPU, while also supporting GPU acceleration for improved performance. They integrate seamlessly with the Healthcare NLP library, just like any other component, and are fully included under the Healthcare NLP license.
| Model Name | Disk Size | Model Size | Modality | Available quantizations | GPU Memory Required |
Token/sec | Max Context Window |
Tasks |
|---|---|---|---|---|---|---|---|---|
| JSL_MedM_v3 | [8.2G, 14G, 21.9G] | 14B | text-only | [q4, q8, q16] | 24GB | [79, 84, 253] | 32,768 | Summarization, Q&A, RAG, and Chat |
| JSL_MedS_v3 | [2.2G, 3.7G, 5.6G] | 3.5B | text-only | [q4, q8, q16] | 10GB | [28.5, 18.7, 50.2] | 131,072 | Summarization, Q&A, RAG |
| JSL_MedS_4B_v5 | [2.4G, 4.0G, 6.1G] | 4B | text-only | [q4, q8, q16] | 16GB | [40, 32, 95] | 32,768 | Summarization, Q&A, RAG |
| JSL_MedS_8B_v4 | [4.6G, 7.8G, 12.2G] | 8B | text-only | [q4, q8, q16] | 16GB | [83, 84, 272] | 32,768 | Summarization, Q&A, RAG |
| JSL_MedS_NER_v4 | [2.2G, 3.7G, 6.0] | 3.5B | text-only | [q4, q8, q16] | 10GB | [28.5, 18.7] | 131,072 | Extract and link medical named entities |
| JSL_MedS_NER_v5 | 6.0G | 3.5B | text-only | q16 | 10GB | — | 131,072 | Clinical trial eligibility parsing |
| JSL_MedS_RAG_v1 | [2.2G, 3.7G, 5.6G] | 3B | text-only | [q4, q8, q16] | 10GB | [30, 20, 53] | 32,768 | LLM component of Retrieval Augmented Generation (RAG) |
| JSL_MedS_Text2SOAP_v1 | 2.2G | 3B | text-only | base | 10GB | 53 | 32,768 | Generate structured SOAP (Subjective, Objective, Assessment, Plan) summaries |
| JSL_MedS_VLM_3B_v1 | [2.5G, 3.6G, 5.6G] | 3B | multimodal | [q4, q8, q16] | 10GB | [8, 11, 40.1] | 128,000 | Extract and link structured medical named entities |
| JSL_MedS_NER_VLM_2B_v2 | [1.5G, 2.1G, 3.3G] | 2B | multimodal | [q4, q8, q16] | 10GB | [25.5, 13.7, 48.9] | 32,768 | Extract and link structured medical named entities |
You can explore these models on our Colab notebook and see how these models can enhance your healthcare workflows.
Introduction
John Snow Labs’ Medical Large Language Models advance Healthcare AI by setting state-of-the-art accuracy on medical LLM benchmarks while remaining small enough to deploy privately. This advances what’s achievable across real-world use cases including clinical assessment, medical question answering, biomedical research synthesis, and diagnostic decision support.
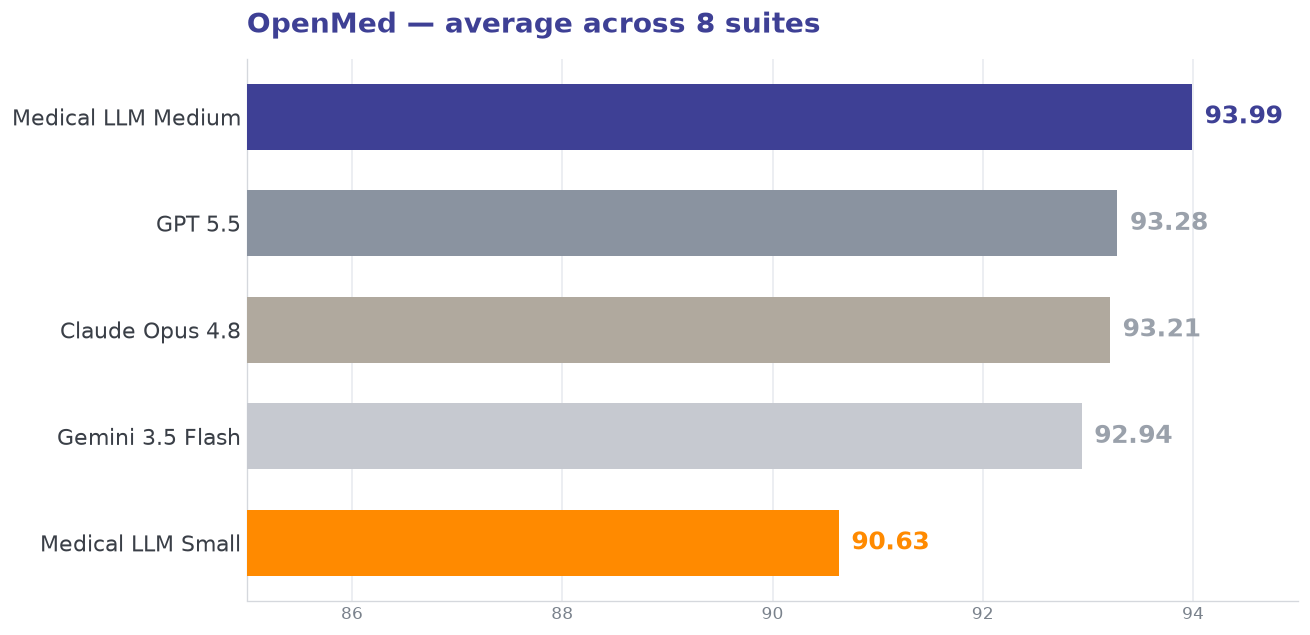
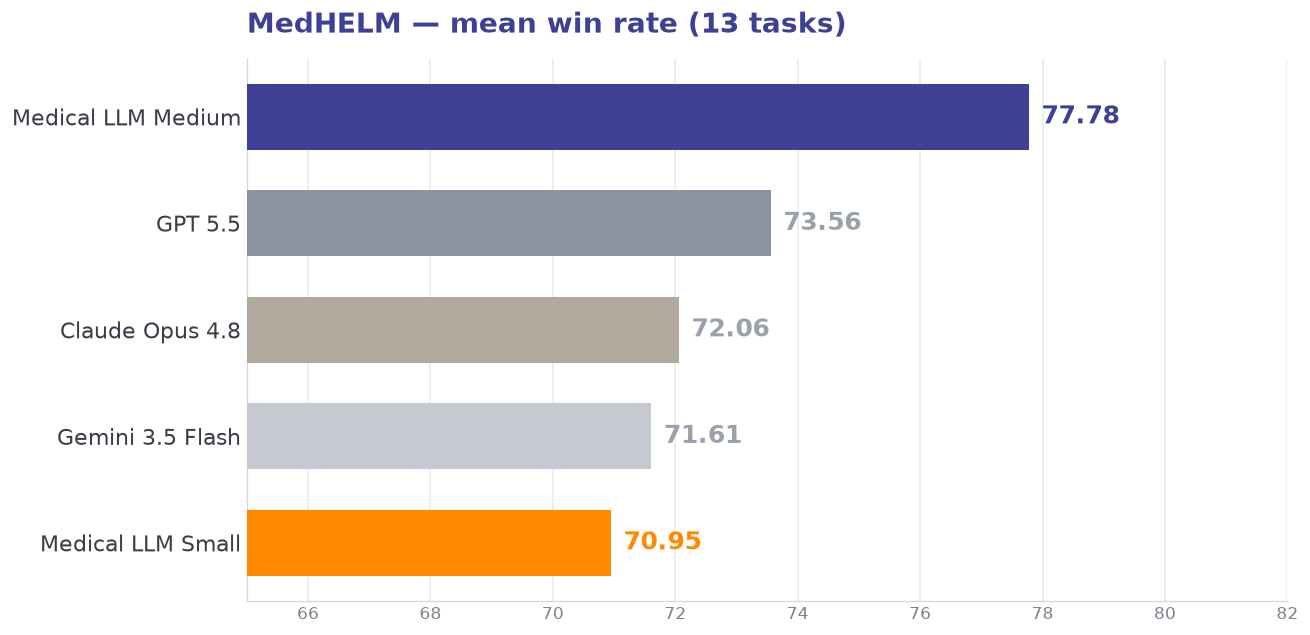
What makes this release special is how strongly the models perform relative to their compute footprint. Medical LLM Medium posts the highest MedHELM mean win rate of every model tested (77.78) and leads the best closed frontier model on OpenMed (93.99). Medical LLM Small clears an OpenMed average of 90.63, making it practical for everyday use in hospitals and clinics where cost, speed, and privacy matter.
OpenMed Benchmark Performance
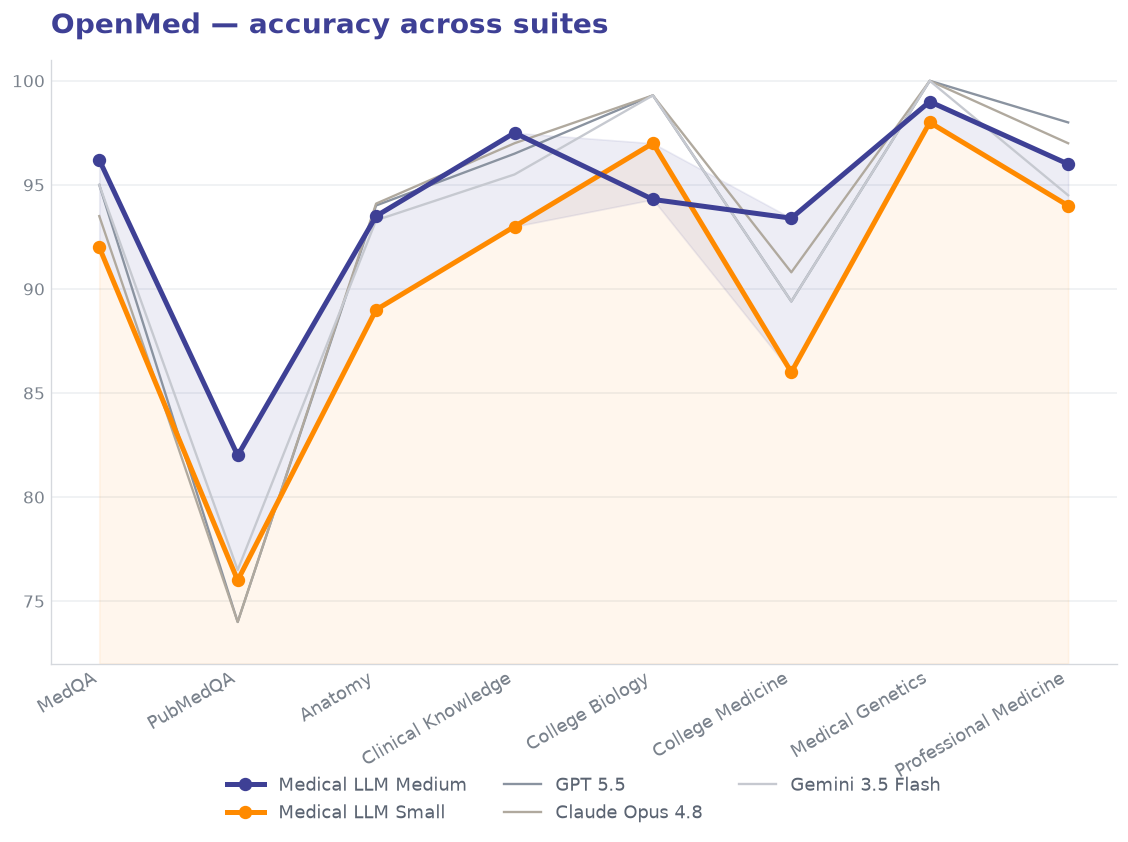
The OpenMed evaluation framework represents one of the most rigorous testing environments for medical AI models, covering a broad spectrum of medical knowledge and clinical reasoning capabilities. It spans eight medical multiple-choice suites — MedQA, PubMedQA, and six MMLU medical subjects. Medical LLM Medium leads the best frontier model, while Medical LLM Small is remarkably strong for its size.
| Model | MedQA | PubMedQA | Anatomy | Clinical Knowledge | College Biology | College Medicine | Medical Genetics | Professional Medicine | Avg |
|---|---|---|---|---|---|---|---|---|---|
| Medical LLM Medium | 96.2 | 82 | 93.5 | 97.5 | 94.3 | 93.4 | 99 | 96 | 93.99 |
| Medical LLM Small | 92 | 76 | 89 | 93 | 97 | 86 | 98 | 94 | 90.63 |
| GPT 5.5 | 95 | 74 | 94.01 | 96.5 | 99.3 | 89.4 | 100 | 98 | 93.28 |
| Claude Opus 4.8 | 93.5 | 74 | 94.1 | 97 | 99.3 | 90.8 | 100 | 97 | 93.21 |
| Gemini 3.5 Flash | 95 | 76.5 | 93.3 | 95.5 | 99.3 | 89.4 | 100 | 94.5 | 92.94 |
Frontier-leading accuracy — private by design. Medical LLM Medium scores 93.99 on OpenMed — ahead of GPT 5.5 (93.28) and Claude Opus 4.8 (93.21) — while being licensed for deployment inside your firewall. Medical LLM Small clears 90 while staying compact enough to run on a single commodity GPU.
JSL-LLM MedHELM Benchmark Analysis
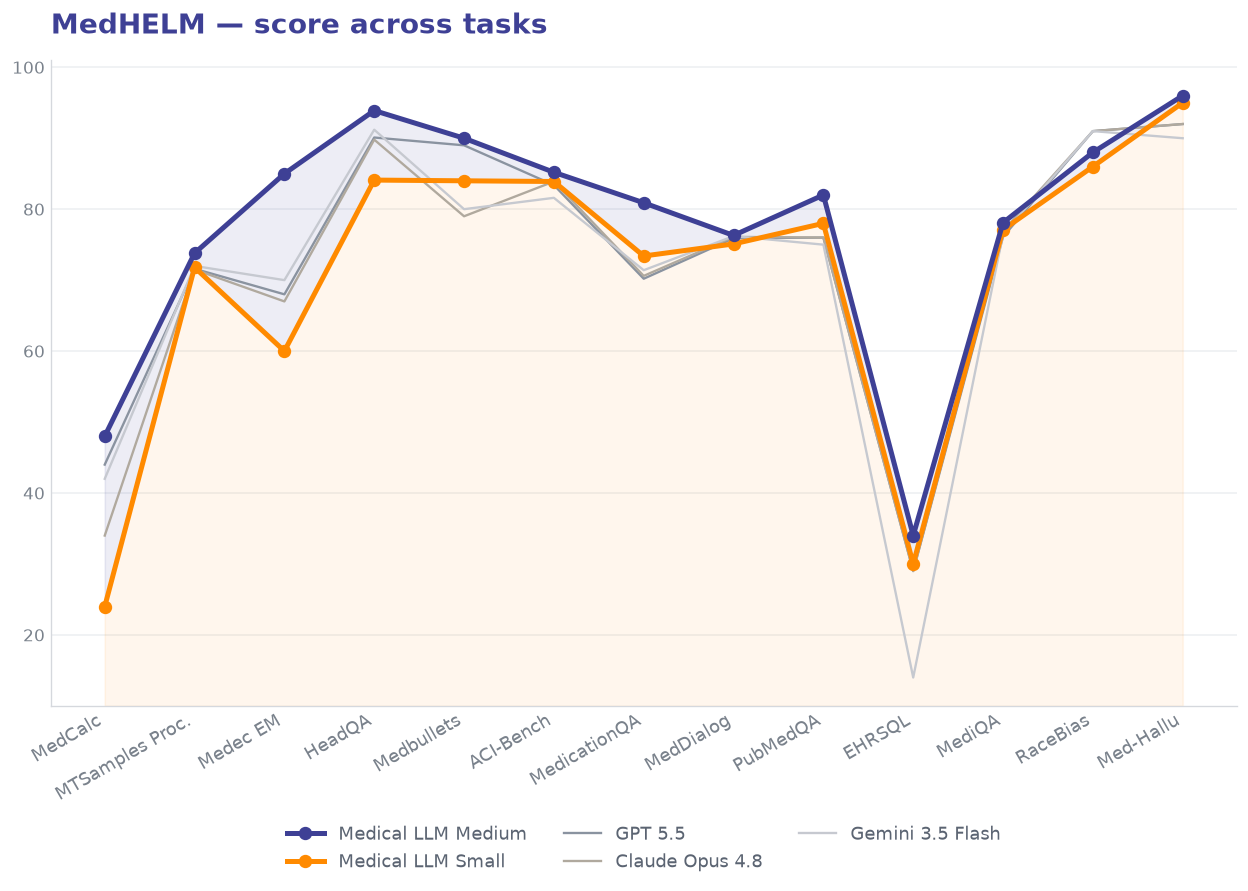
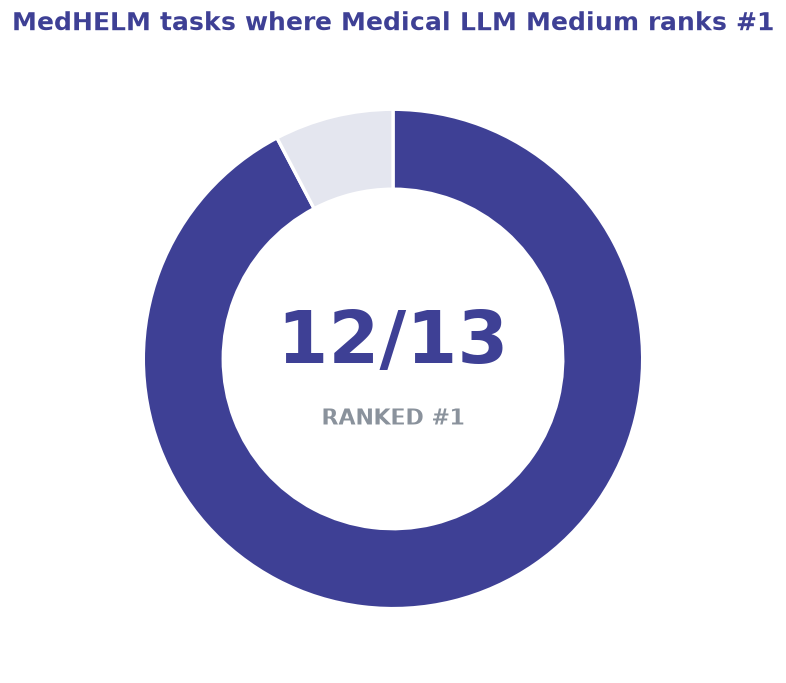
MedHELM spans thirteen clinical tasks across documentation, coding, safety, dialogue, and reasoning. Medical LLM Medium posts the highest mean win rate of every model tested, and records the best score on 12 of the 13 tasks.
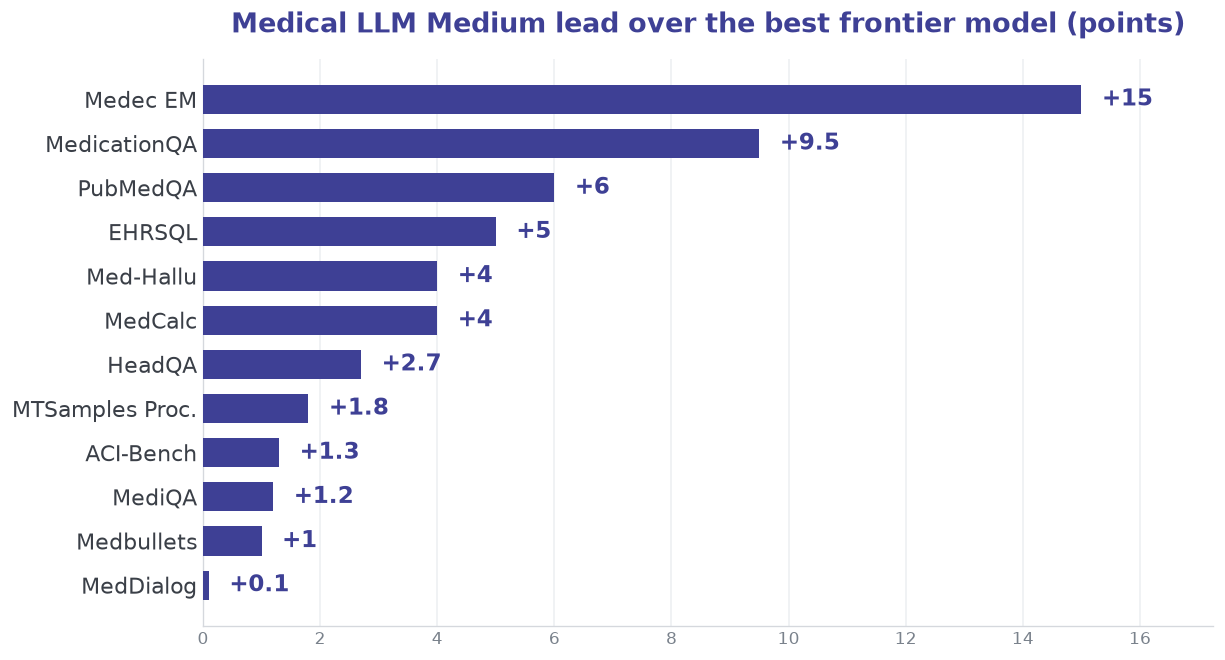
| Benchmark | Medical LLM Medium | Medical LLM Small | GPT 5.5 | Claude Opus 4.8 | Gemini 3.5 Flash |
|---|---|---|---|---|---|
| Mean win rate | 77.78 | 70.95 | 73.56 | 72.06 | 71.61 |
| MedCalc | 48 | 24 | 44 | 34 | 42 |
| MTSamples Proc. | 73.8 | 71.8 | 71.6 | 71.5 | 72 |
| Medec EM | 85 | 60 | 68 | 67 | 70 |
| HeadQA | 93.9 | 84.1 | 90.1 | 89.8 | 91.2 |
| Medbullets | 90 | 84 | 89 | 79 | 80 |
| ACI-Bench | 85.2 | 83.9 | 83.4 | 83.9 | 81.6 |
| MedicationQA | 80.9 | 73.4 | 70.2 | 70.6 | 71.4 |
| MedDialog | 76.3 | 75.1 | 75.9 | 76.1 | 76.2 |
| PubMedQA | 82 | 78 | 76 | 76 | 75 |
| EHRSQL | 34 | 30 | 29 | 29 | 14 |
| MediQA | 78.1 | 77.1 | 76.1 | 76.9 | 76.5 |
| RaceBias | 88 | 86 | 91 | 91 | 91 |
| Med-Hallu | 96 | 95 | 92 | 92 | 90 |
Strongest where clinical work is hardest. Medical LLM Medium records the best score on 12 of the 13 MedHELM tasks, with its largest margins on clinical error detection (Medec +15), medication QA (+9.5), biomedical research comprehension (PubMedQA +6), and hallucination control.
How the Models Compare
Three signals matter for a clinical deployment: how often the model ranks first, whether a John Snow Labs model can match closed frontier systems, and how well it resists hallucination.
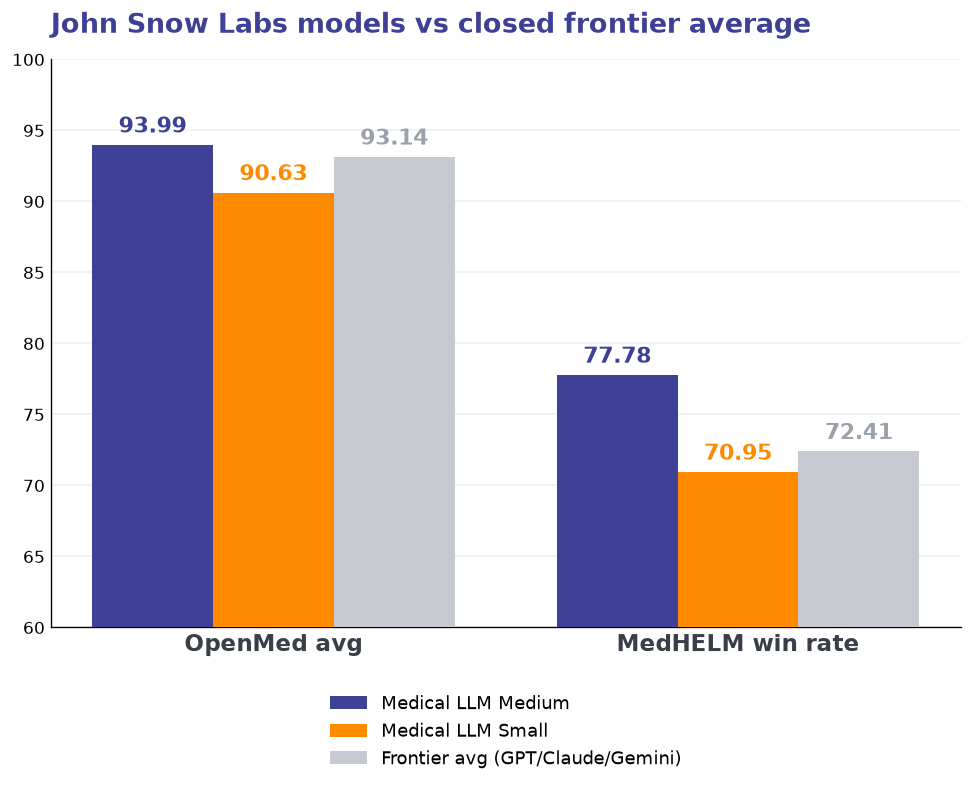
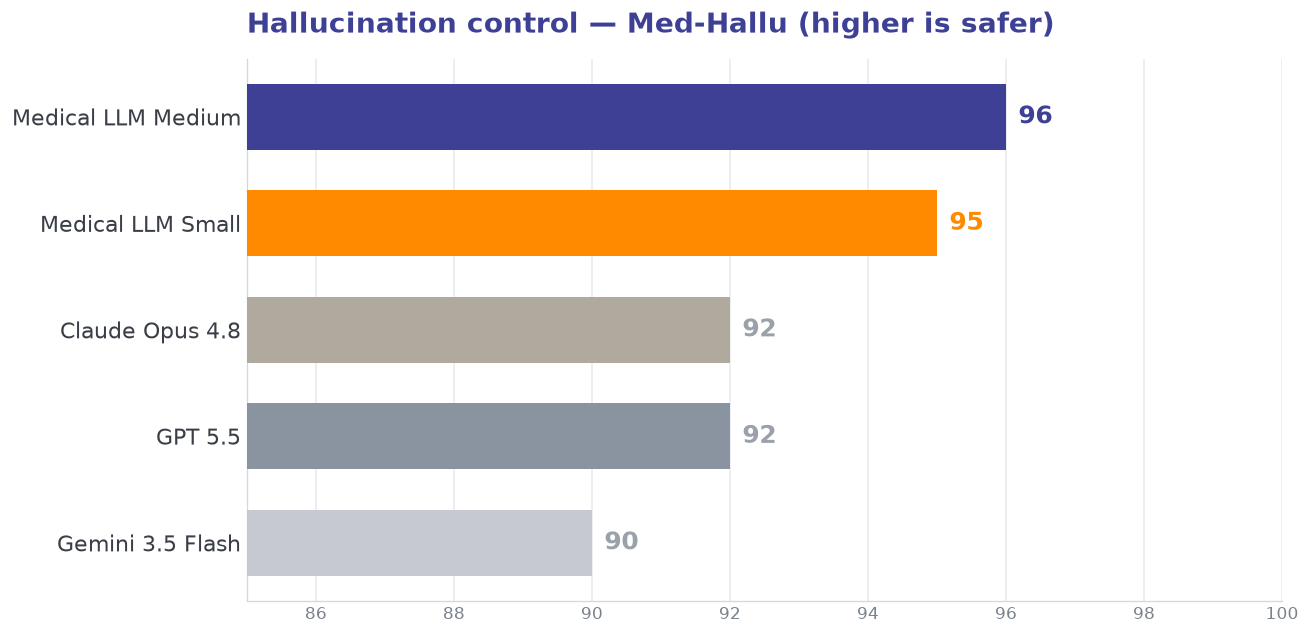
A John Snow Labs model leads the closed frontier on OpenMed (93.99 vs 93.14 average) while beating it outright on MedHELM (77.78 vs 72.41 average). On hallucination — the metric that decides whether a model is safe in front of clinicians — both John Snow Labs models rank first.
Red-Teaming Evaluation Results
Out of 1000 red-teaming questions across 148 medical categories, Medical LLM Medium passed about 940 (94%), compared to 850 for GPT-5.5 (85%), 830 for Claude Opus 4.8 (83%), and only 790 for Gemini 3.5 Flash (79%) — making Medical LLM Medium the most robust model in this evaluation and outperforming larger private models despite its smaller size.
Vision OCR
Industry Benchmarks and Academic Research strongly agree that Task-optimized OCR models beat general-purpose frontier systems on crucial tasks for document pipelines: grounding every token to a precise bounding box, and turning a page into schema-valid structured output. At John Snow Labs, we’ve built a focused pair of OCR models for exactly those tasks.
Vision OCR LLM and Vision OCR Structured LLM are benchmarked head-to-head against the leading closed frontier systems (GPT 5.5, Claude Opus 4.8, and Gemini 3.5 Flash) across table structure, bounding-box grounding, and structured JSON. Closed frontier models should not run on patient records, ours can. Licensed for on-premise or private cloud deployment, keeps PII and PHI inside your infrastructure, HIPAA-friendly, without giving up accuracy where it matters most.
Vision OCR Offering
| Model Name | Recommended GPU Memory | Max Sequence Length | Max KV-Cache | Tensor Parallel Sizes | Supported Platforms |
|---|---|---|---|---|---|
| Vision-OCR-LLM | ~6 GB | 32K | 4 GB | 1, 2, 4 | On-Premise AWS Azure Databricks Snowflake |
| Vision-OCR-Structured-LLM | ~32 GB | 128K | 17 GB | 1, 2, 4 | On-Premise AWS Azure Databricks Snowflake |
Note: bf16 serving, GB = 10⁹ bytes. Recommended GPU Memory covers measured model weights, KV cache at each model’s max context (128K for Vision OCR Structured LLM, 32K for Vision OCR LLM), and ~8% activation/runtime overhead, per DJL’s LMI Deployment Guide. Typical OCR context (~8K) is far smaller — ~19 GB / ~3 GB, single-GPU.
- Vision OCR LLM: Grounding specialist. Word-level OCR with precise bounding boxes, single-GPU. AWS Marketplace
- Vision OCR Structured LLM: Structure specialist. Document to schema-constrained JSON. AWS Marketplace
Introduction
John Snow Labs’ Vision OCR models hit competitive accuracy on the benchmarks that matter in production while staying small enough to deploy privately. Vision OCR LLM posts the top table-structure score of every model tested (0.784 TEDS-S) and top-tier grounding (0.938) on a single commodity GPU; Vision OCR Structured LLM handles schema-constrained JSON extraction (0.708) ahead of two of the three closed frontier systems. All models run inside your firewall, where the closed frontier cannot, ideal for hospitals and clinics where cost, speed, and privacy matter.
Table Structure Recognition Performance
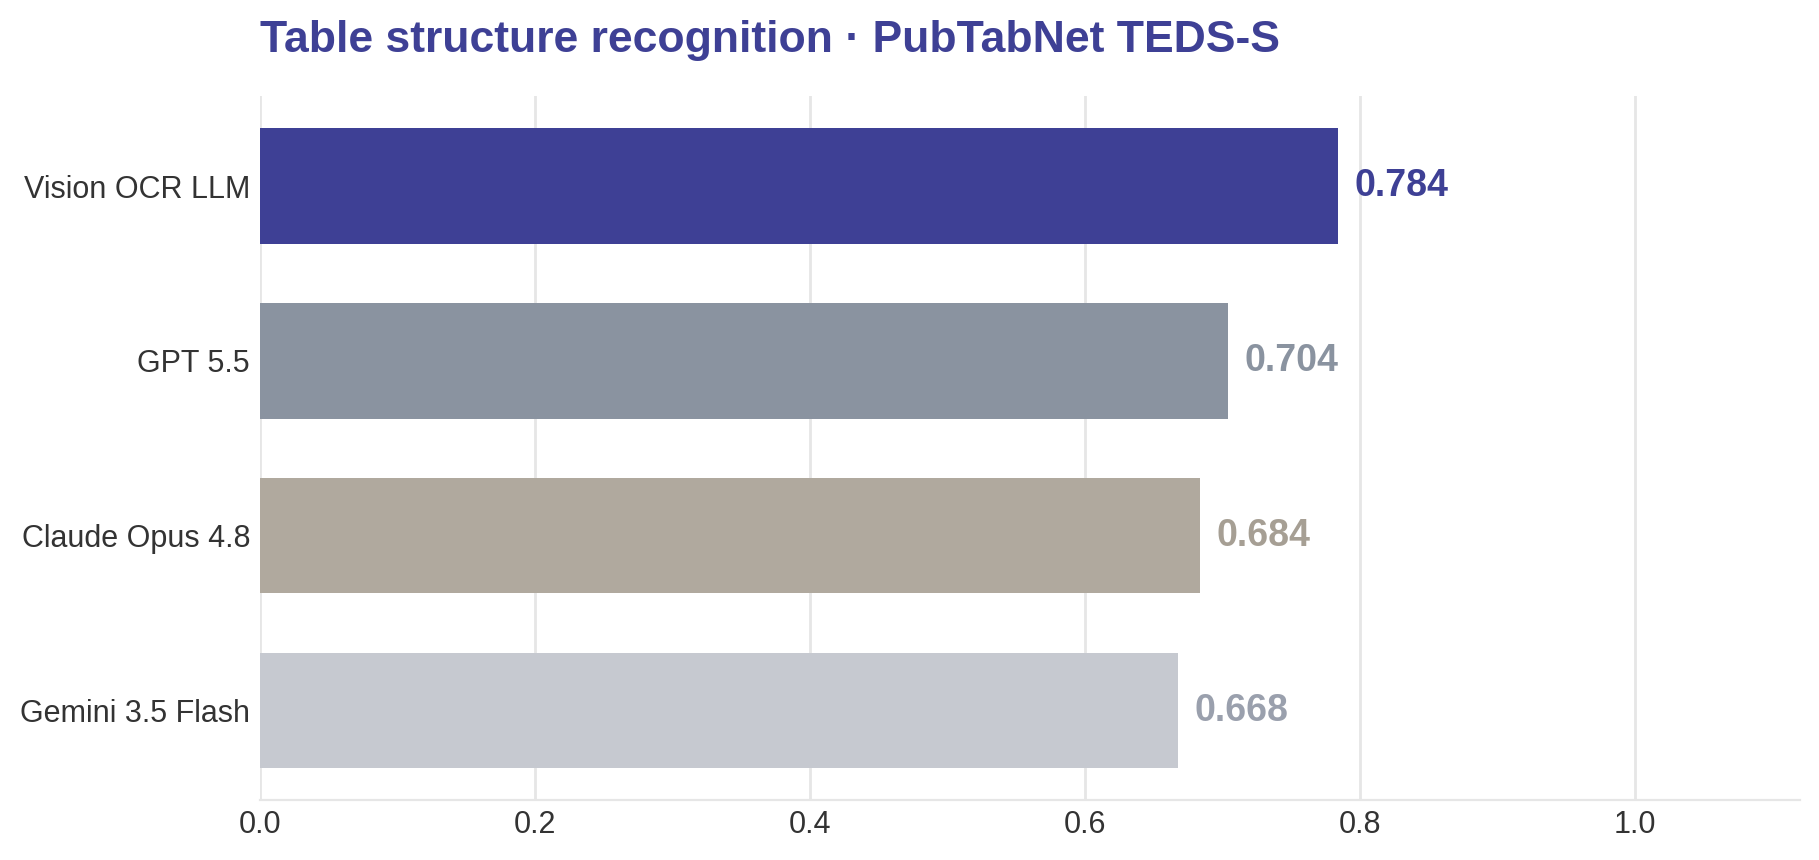
TEDS-S (structure-only tree-edit-distance similarity) scores table-structure recovery on a complexity-balanced 50-table slice of PubTabNet. Vision OCR LLM beats every closed frontier model.
| Model | TEDS-S |
|---|---|
| Vision OCR LLM | 0.784 |
| GPT 5.5 | 0.704 |
| Claude Opus 4.8 | 0.684 |
| Gemini 3.5 Flash | 0.668 |
Leads the frontier on table structure, privately. Vision OCR LLM posts the highest TEDS-S of every model tested (0.784), 8 points ahead of the best frontier system, running single-GPU inside your firewall.
Dataset: PubTabNet validation set. 50 tables selected by structural complexity — every table scored (spanning cells, row and cell counts), split into 5 complexity quintiles, 10 sampled evenly from each — so the slice spans simple to very dense rather than favoring either. All four models on the identical 50.
Bounding-Box Grounding OCR Performance
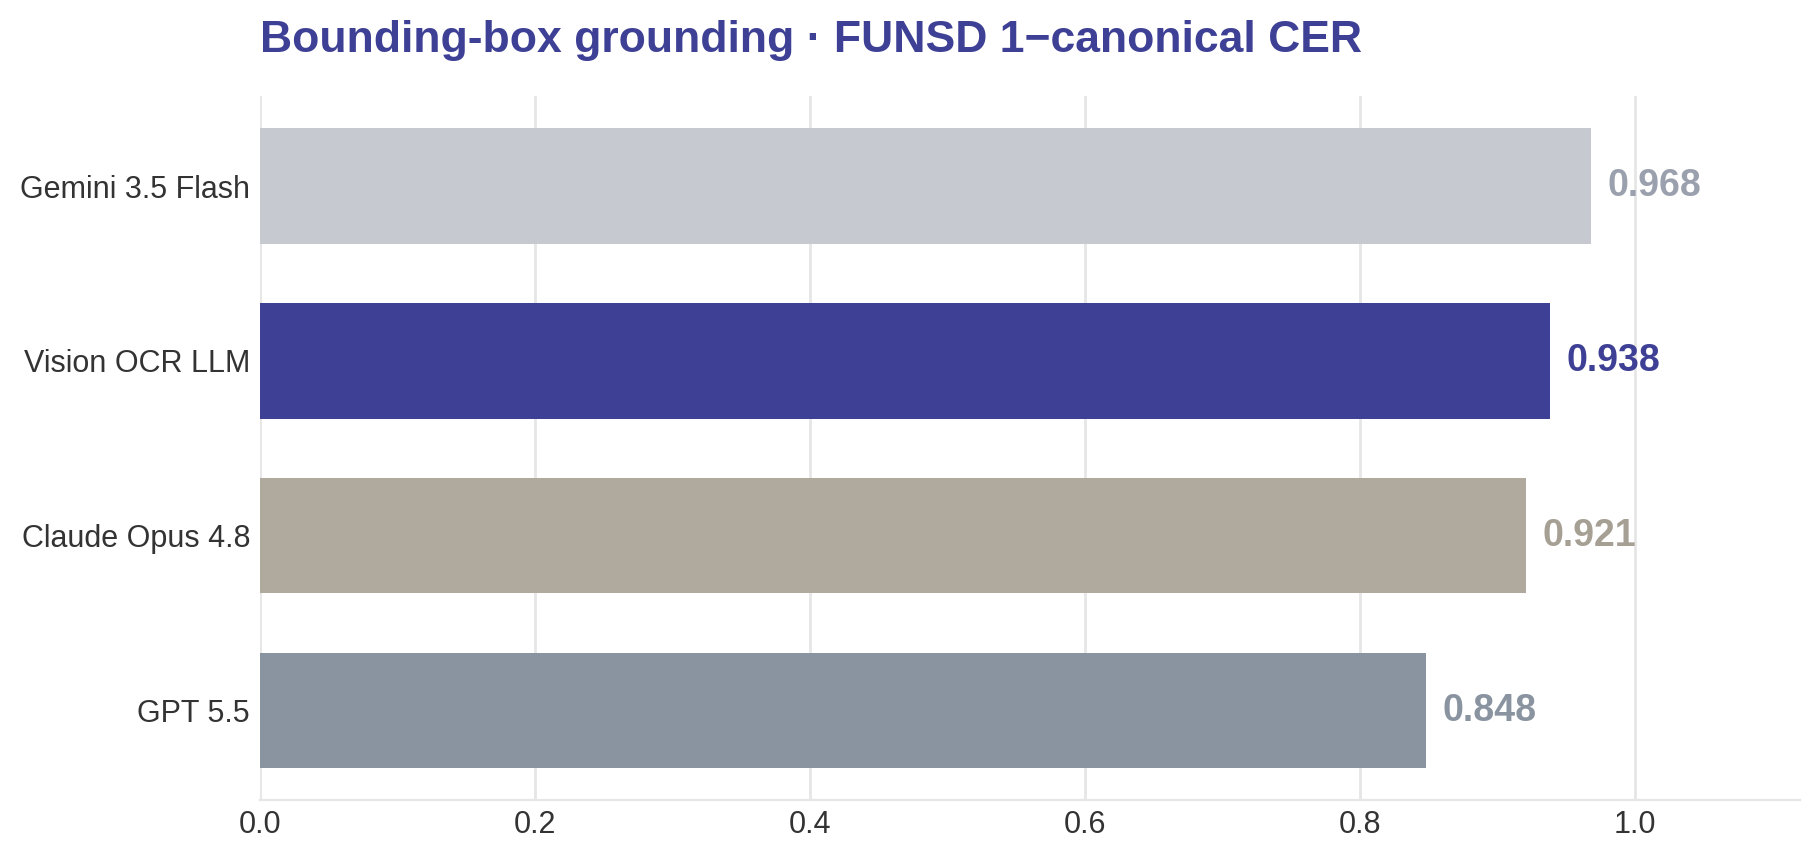
Grounding is scored on FUNSD as 1 minus canonical CER (the reading-order, region-matched metric behind our published AWS Marketplace figure). Predicted boxes are first IoU-matched to gold regions (0.78 overlap threshold), then CER measures how accurately it read the text inside those matched regions. Vision OCR LLM lands in the top tier, ahead of GPT 5.5 and Claude Opus 4.8, and is the only model here that pairs a top-tier score with full-page coverage.
| Model | 1 − canonical CER |
|---|---|
| Vision OCR LLM | 0.938 |
| GPT 5.5 | 0.848 |
| Claude Opus 4.8 | 0.921 |
| Gemini 3.5 Flash | 0.968 |
Top-tier grounding, full-page coverage. Vision OCR LLM scores 0.938, ahead of GPT 5.5 and Claude Opus 4.8. Canonical CER rewards only tightly localized regions, so a high frontier score can mean partial page coverage; Vision OCR LLM combines its score with full-page coverage.
Dataset: FUNSD official 2019 test split — all 50 test forms (the complete test set, not a sub-sample), with word-level box + text ground truth. All four models on the identical 50.
Structured JSON Extraction
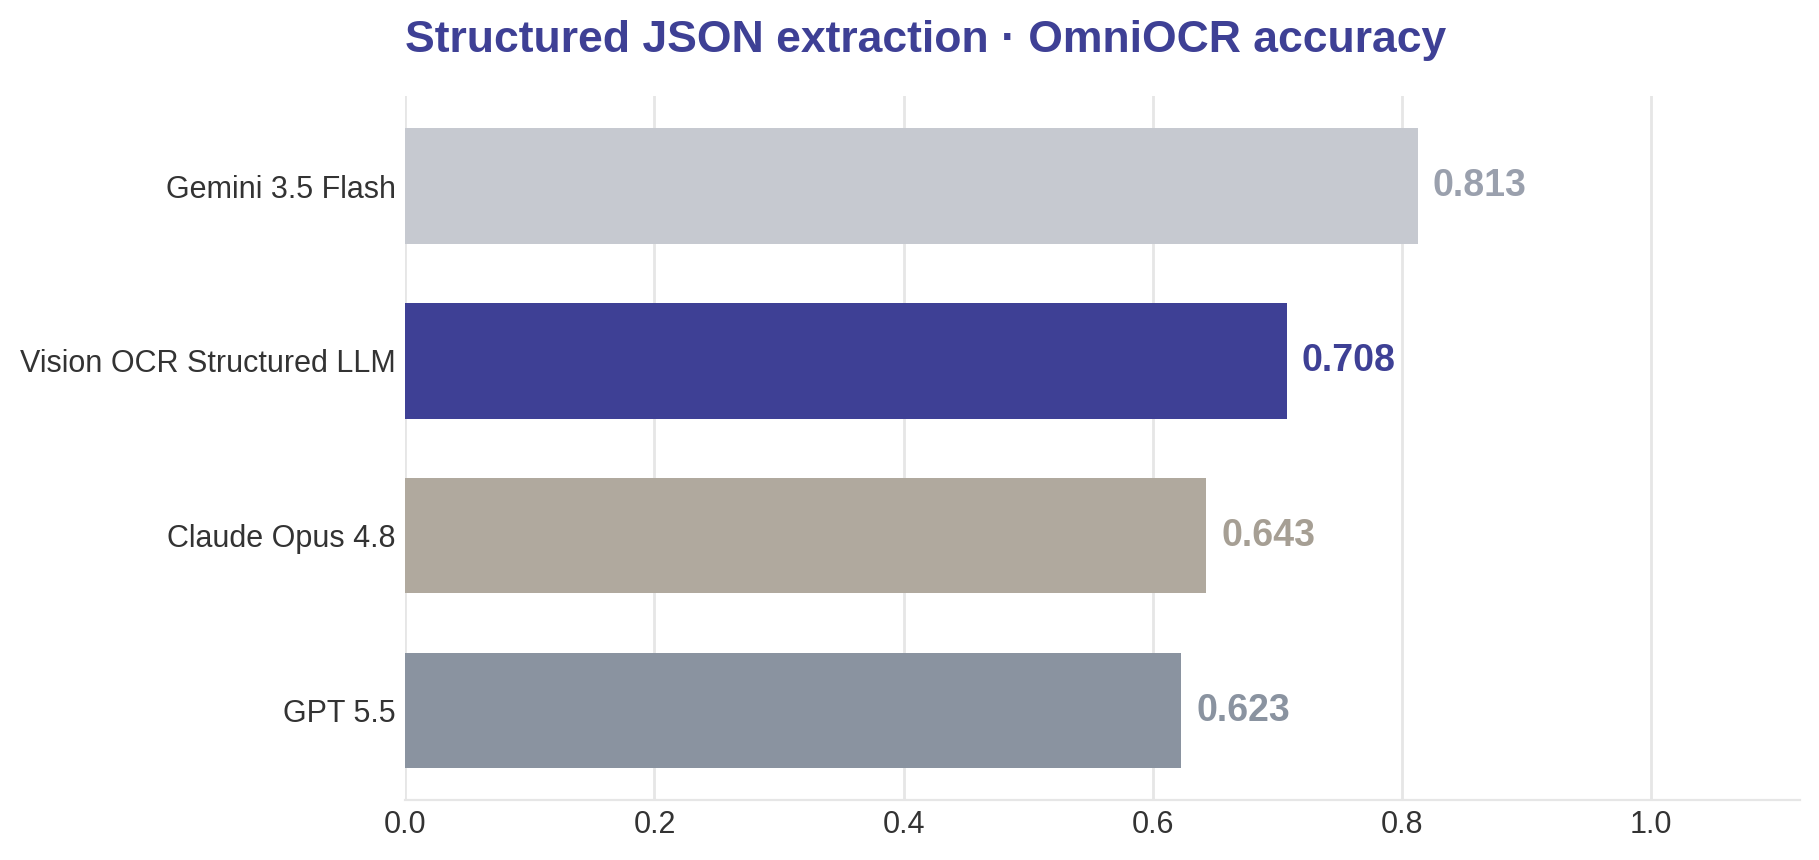
OmniOCR scores schema-constrained document-to-JSON as field accuracy, the task production extraction pipelines are built on. Vision OCR Structured LLM is competitive with the frontier, ahead of GPT 5.5 and Claude Opus 4.8, and matches its published AWS Marketplace figure (0.714).
| Model | JSON accuracy |
|---|---|
| Vision OCR Structured LLM | 0.708 |
| GPT 5.5 | 0.623 |
| Claude Opus 4.8 | 0.643 |
| Gemini 3.5 Flash | 0.813 |
Frontier-competitive structured extraction, private by design. Vision OCR Structured LLM reaches 0.708 JSON accuracy, ahead of GPT 5.5 and Claude Opus 4.8, while licensed for deployment inside your firewall.
Dataset: OmniOCR (getomni-ai/ocr-benchmark, pinned revision), test split — the first 100 documents. All four models on the identical 100.
How the Models Compare
Across all three task families, a John Snow Labs model beats the closed-frontier average, each model shown on its target task.
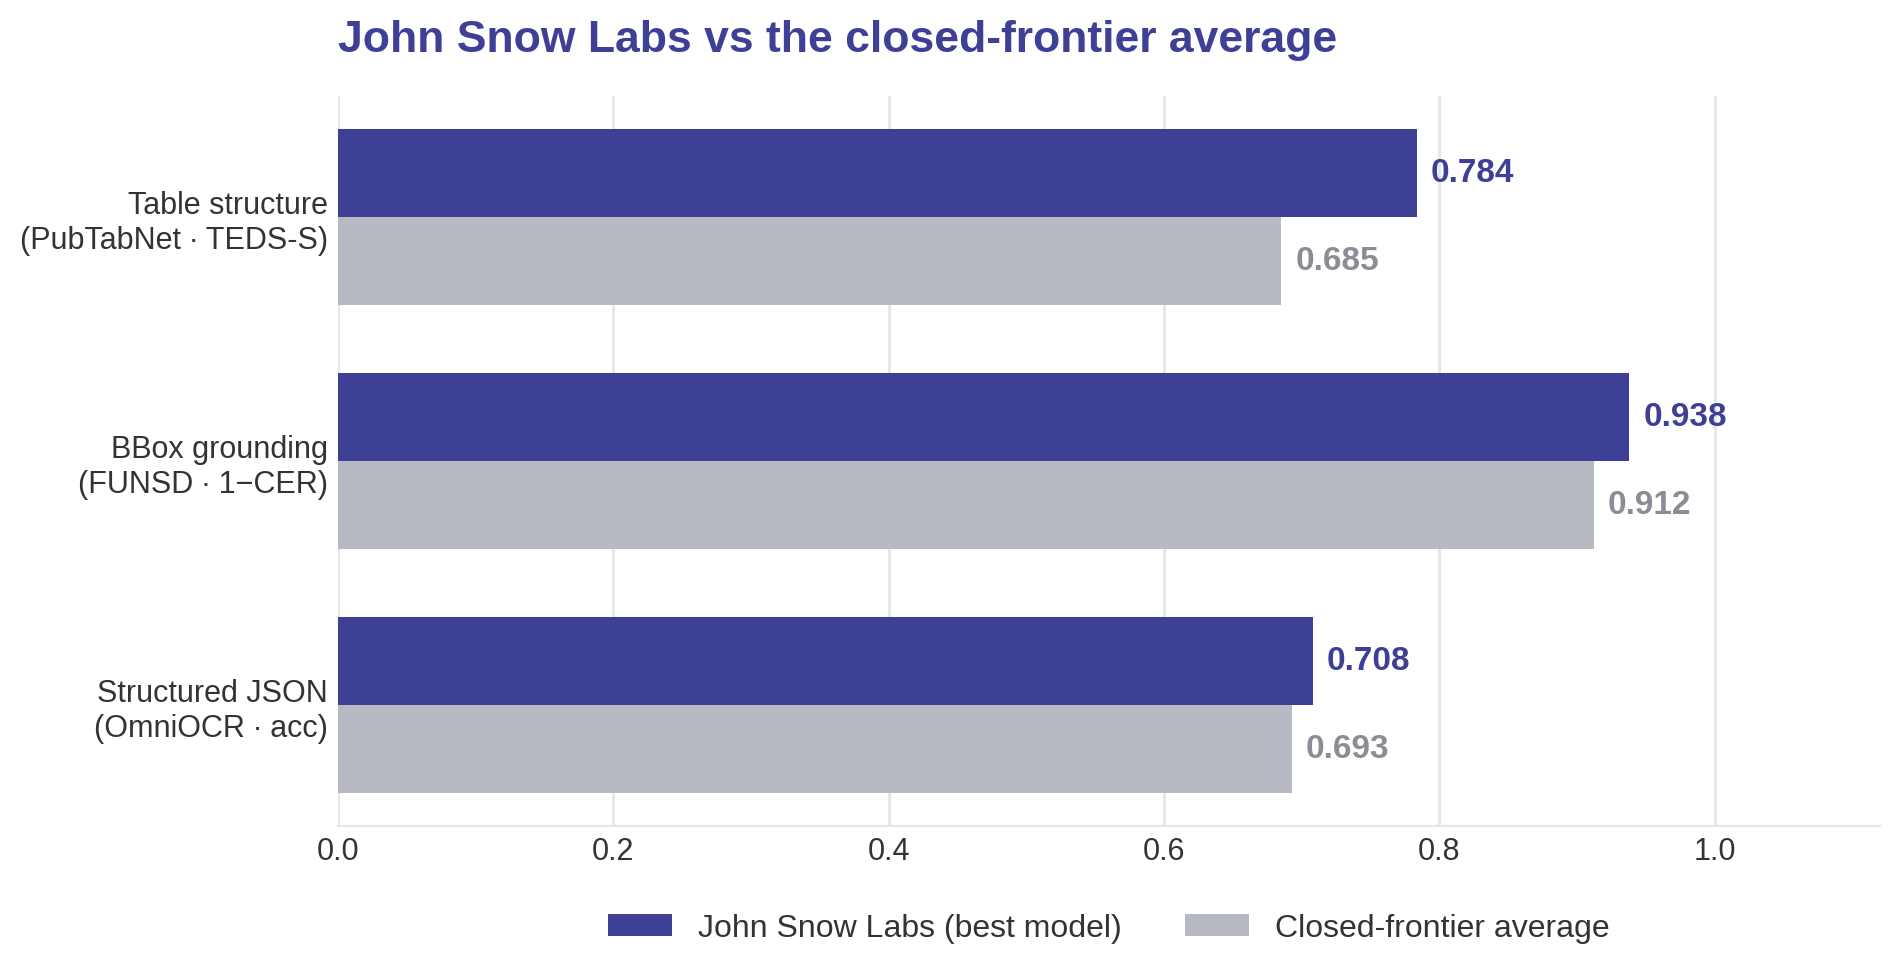
Vision OCR LLM leads on table structure (0.784) and top-tier grounding (0.938, with full-page coverage); Vision OCR Structured LLM stays ahead of two of three frontier systems on structured JSON. The whole family runs single-GPU on-premise, which the closed frontier cannot.
All numbers measured on our own harness under identical conditions (same prompt, 0 errored docs). BBox is shown as 1 − canonical CER (higher is better) — the reading-order, region-matched metric behind our published AWS Marketplace figures (raw canonical CER 0.039 for Vision OCR LLM on FUNSD; 0.714 JSON accuracy for Vision OCR Structured LLM on OmniOCR).
Partner With Us
We’re committed to helping you stay at the cutting edge of medical AI. Whether you’re building decision support tools, clinical chatbots, or research platforms — our team is here to help.
Book a call with our experts to:
- Discuss your specific use case
- Get a live demo of the Medical LLMs
- Explore tailored deployment options.